2 2
3> For the complete documentation index, see [llms.txt](/llms.txt). Markdown versions of documentation pages are available by appending `.md` to the page URL.3> For the complete documentation index, see [llms.txt](/llms.txt). Markdown versions of documentation pages are available by appending `.md` to the page URL.
4 4
5This guide covers the core set of principles you can apply to improve latency across a wide variety of LLM-related use cases. These techniques come from working with a wide range of customers and developers on production applications, so they should apply regardless of what you're building—from a granular workflow to an end-to-end chat application.5Measure where users wait before changing the model or prompt.
6 6
7Although there are many individual techniques, this guide groups them into **seven principles** that represent a high-level taxonomy of approaches for improving latency.7- **Time to first token (TTFT)** measures how long an API request takes to start returning content. For streaming text in the Responses API, time the request from when you send it until you receive the first nonempty `response.output_text.delta`.
8- **End-to-end latency** measures how long the user waits for the complete result. Time it from the user's action through retrieval, model and tool calls, retries, and rendering.
8 9
9At the end, we'll walk through an [example](#example) to see how they can be applied.10Compare the median (p50) and the 95th percentile (p95) on representative traffic. Group similar requests by model, service tier, and task. Record input, cached input, and output tokens alongside the timings. If TTFT looks good but users still see a blank screen, time the work before the model call and check when the client displays the first text.
10 11
11### Seven principles12### Seven principles
12 13
20 21
21## Process tokens faster22## Process tokens faster
22 23
23**Inference speed** is probably the first thing that comes to mind when addressing latency (but as you'll see soon, it's far from the only one). This refers to the actual **rate at which the LLM processes tokens**, and is often measured in TPM (tokens per minute) or TPS (tokens per second).24Choose a model using examples from your workload. For a focused task like routing a support ticket, try [`gpt-6-luna`](https://developers.openai.com/api/docs/models/gpt-6-luna). For more demanding work, use the [model selection guide](https://developers.openai.com/api/docs/guides/model-selection) to choose a comparison model. Keep the fastest configuration that meets your quality target, including on difficult cases.
24 25
25The main factor that influences inference speed is **model size**—smaller models usually run faster (and cheaper), and when used correctly can even outperform larger models. To maintain high-quality performance with smaller models, you can explore:26If you need to keep the same model, compare Standard processing with [Fast mode](https://developers.openai.com/api/docs/guides/fast-mode) or [Ultrafast mode](https://developers.openai.com/api/docs/guides/ultrafast-mode) where supported. Both charge a premium. Compare the same prompts and output lengths, and record the `service_tier` returned in each response.
26
27- using a longer, [more detailed prompt](https://developers.openai.com/api/docs/guides/prompt-engineering#prompt-engineering),
28- adding (more) [few-shot examples](https://developers.openai.com/api/docs/guides/prompt-engineering#few-shot-learning), or
29- [fine-tuning](https://developers.openai.com/api/docs/guides/model-optimization) / distillation.
30
31You can also employ inference optimizations like our [**Predicted outputs**](https://developers.openai.com/api/docs/guides/predicted-outputs) feature. Predicted outputs let you significantly reduce latency of a generation when you know most of the output ahead of time, such as code editing tasks. By giving the model a prediction, the LLM can focus more on the actual changes, and less on the content that will remain the same.
32
33
34
35Other factors that affect inference speed are the amount of
36 **compute** you have available and any additional
37 **inference optimizations** you employ.
38
39
40 Most people can't influence these factors directly, but if you're curious, and
41 have some control over your infra, **faster hardware** or
42 **running engines at a lower saturation** may give you a modest
43 TPM boost. And if you're down in the trenches, there's a myriad of other
44 [inference optimizations](https://lilianweng.github.io/posts/2023-01-10-inference-optimization/)
45 that are a bit beyond the scope of this guide.
46 27
28For long answers, measure visible output speed in tokens per second. Count the text tokens received after the first text event and divide by the time from the first text event to the last. A streamed event can contain multiple tokens. A tokens-per-minute rate limit measures how much traffic you can send across requests.
47 29
30For Chat Completions on a supported model, [Predicted Outputs](https://developers.openai.com/api/docs/guides/predicted-outputs) can reduce generation time when you already know most of the answer, such as when editing a few lines in a file. Check model and parameter compatibility before using this option.
48 31
49## Generate fewer tokens32## Generate fewer tokens
50 33
51Generating tokens is almost always the highest latency step when using an LLM: as a general heuristic, **cutting 50% of your output tokens may cut ~50% of your latency**. The way you reduce your output size will depend on output type:34If an answer starts quickly but takes too long to finish, inspect what the model generates.
52
53If you're generating **natural language**, **asking the model to be more concise** ("under 20 words" or "be brief") may help. You can also use few-shot examples and/or fine-tuning to teach the model shorter responses.
54
55If you're generating **structured output**, try to **minimize your output syntax** where possible: shorten function names, omit named arguments, coalesce parameters, etc.
56 35
57Finally, while not common, you can also use `max_tokens` or `stop_tokens` to end your generation early.36- **Visible text.** Ask for the amount of detail the user needs, such as “Give the next step in one sentence.” On supported Responses API models, lower [`text.verbosity`](https://developers.openai.com/api/docs/guides/deployment-checklist#set-up-textverbosity) for shorter answers.
37- **Reasoning.** For routine extraction or classification, try a lower supported [`reasoning.effort`](https://developers.openai.com/api/docs/guides/reasoning#reasoning-effort). Compare accuracy and time to first text on the same examples. Check `usage.output_tokens_details.reasoning_tokens` to see how much reasoning the model used.
38- **Structured output.** Request only the fields your application consumes. Compute values you already know, such as a message count, in application code. Use [Structured Outputs](https://developers.openai.com/api/docs/guides/structured-outputs) when the response must follow a schema.
58 39
59Always remember: an output token cut is a (milli)second earned!40In the Responses API, `max_output_tokens` caps both reasoning and visible output tokens. A low cap can leave the response `incomplete`, even before it produces visible text. Use the cap as a budget and check response status before consuming a partial answer.
60 41
61## Use fewer input tokens42## Use fewer input tokens
62 43
63While reducing the number of input tokens does result in lower latency, this is not usually a significant factor—**cutting 50% of your prompt may only result in a 1–5% latency improvement**. Unless you're working with truly massive context sizes (documents, images), you may want to spend your efforts elsewhere.44A long prompt can delay the first token, especially when much of the input is new. Filter search results for relevance, strip markup you don't need, and send only the context required to answer accurately.
64 45
65That being said, if you _are_ working with massive contexts (or you're set on squeezing every last bit of performance _and_ you've exhausted all other options) you can use the following techniques to reduce your input tokens:46For repeated inputs, put stable instructions, examples, and tool definitions first. In multi-turn conversations, [keep the prefix unchanged](https://developers.openai.com/api/docs/guides/preserved-reasoning) and append new messages and tool results. [Prompt caching](https://developers.openai.com/api/docs/guides/prompt-caching) can reuse an eligible exact prefix match. In the Responses API, inspect `usage.input_tokens_details.cached_tokens` and compare TTFT for requests with and without cache hits.
66
67- **Fine-tuning the model**, to replace the need for lengthy instructions / examples.
68- **Filtering context input**, like pruning RAG results, cleaning HTML, etc.
69- **Maximize shared prompt prefix**, by putting dynamic portions (for example, RAG results and history) later in the prompt. This makes your request more [KV cache](https://medium.com/@joaolages/kv-caching-explained-276520203249)-friendly (which most LLM providers use) and means fewer input tokens are processed on each request.
70
71Check out our docs to learn more about how [prompt
72 caching](https://developers.openai.com/api/docs/guides/prompt-engineering#save-on-cost-and-latency-with-prompt-caching)
73 works.
74 47
75## Make fewer requests48## Make fewer requests
76 49
77Each time you make a request, you incur some round-trip latency—this can start to add up.50Each sequential model or tool call adds another wait. Combine steps when one request has all the information it needs. For example, a model can turn a customer's follow-up into a standalone search query and decide whether a lookup is necessary in the same response. A reply that depends on a lookup still needs its result.
78
79If you have sequential steps for the LLM to perform, instead of firing off one request per step consider **putting them in a single prompt and getting them all in a single response**. You'll avoid the additional round-trip latency, and potentially also reduce complexity of processing multiple responses.
80 51
81An approach to doing this is by collecting your steps in an enumerated list in the combined prompt, and then requesting the model to return the results in named fields in a JSON object. This way, you can parse and reference each result.52If your agent makes many short, sequential tool calls, try [WebSocket mode](https://developers.openai.com/api/docs/guides/websocket-mode). Reuse the connection and continue from the prior response with `previous_response_id`, sending only new input items and tool results. This reduces overhead between turns.
82 53
83## Parallelize54## Parallelize
84 55
85Parallel processing can be powerful when performing multiple steps with an LLM.56Run independent work concurrently. For example, once you have an order ID, you can look up its shipment status while fetching the return policy. An answer that needs both can start as soon as the slower lookup finishes. On supported models, [async tool calling](https://developers.openai.com/api/docs/guides/async-tool-calling) also lets the model continue independent work while your application runs a tool.
86 57
87If the steps **are _not_ strictly sequential**, you can **split them out into parallel calls**. Two shirts take just as long to dry as one.58For a likely but uncertain branch, consider starting a read-only lookup early and discarding it if it's unnecessary. Measure the extra cost on a wrong guess. Wait for required checks before displaying a result or taking an action such as issuing a refund.
88
89If the steps **_are_ strictly sequential**, however, you might still be able to **leverage speculative execution**. This is particularly effective for classification steps where one outcome is more likely than the others (for example, moderation).
90
911. Start step 1 and step 2 simultaneously (for example, input moderation and story generation)
922. Verify the result of step 1
933. If result was not the expected, cancel step 2 (and retry if necessary)
94
95If your guess for step 1 is right, then you essentially got to run it with zero added latency!
96 59
97## Make your users wait less60## Make your users wait less
98 61
99There's a huge difference between **waiting** and **watching progress happen**—make sure your users experience the latter. Here are a few techniques:62For interactive text over HTTP, [stream the response](https://developers.openai.com/api/docs/guides/streaming-responses) with `stream: true` and display text as it arrives. Streaming lets the user start reading before generation finishes. Time to the first visible text still depends on the request, including any reasoning or tool work before the answer.
100 63
101- **Streaming**: The single most effective approach, as it cuts the _waiting_ time to a second or less. (ChatGPT would feel pretty different if you saw nothing until each response was done.)64If you check or moderate output before displaying it, buffer enough text to perform that check. For longer tasks, show actual progress, such as “Looking up your order,” while the lookup runs. When the user can return later, [Background mode](https://developers.openai.com/api/docs/guides/background) lets your application submit the work and retrieve the result asynchronously.
102- **Chunking**: If your output needs further processing before being shown to the user (moderation, translation), consider **processing it in chunks** instead of all at once. Do this by streaming to your back end, then sending processed chunks to your front end.
103- **Show your steps**: If you're taking multiple steps or using tools, surface this to the user. The more real progress you can show, the better.
104- **Loading states**: Spinners and progress bars go a long way.
105
106Note that while **showing your steps & having loading states** have a mostly
107psychological effect, **streaming & chunking** genuinely do reduce overall
108latency once you consider the app + user system: the user will finish reading a response
109sooner.
110 65
111## Don't default to an LLM66## Don't default to an LLM
112 67
113Language models are powerful and versatile, and are therefore sometimes used in cases where a **faster classical method** would be more appropriate. Identifying such cases may allow you to cut your latency significantly. Consider the following examples:68Use application code when you already know the answer. Render an order status from the order API, use a template to confirm a refund that succeeded, or show search results directly. Each of these can remove a model call from the user's wait.
114
115- **Hard-coding:** If your **output** is highly constrained, you may not need an LLM to generate it. Action confirmations, refusal messages, and requests for standard input are all great candidates to be hard-coded. (You can even use the age-old method of coming up with a few variations for each.)
116- **Pre-computing:** If your **input** is constrained (for example, category selection), you can generate multiple responses in advance, and just make sure you never show the same one to a user twice.
117- **Leveraging UI:** Summarized metrics, reports, or search results are sometimes better conveyed with classical, bespoke UI components rather than LLM-generated text.
118- **Traditional optimization techniques:** An LLM application is still an application; binary search, caching, hash maps, and runtime complexity are all _still_ useful in a world of language models.
119 69
120## Example70## Example
121 71
122Let's now look at a sample application, identify potential latency optimizations, and propose some solutions!
123
124We'll be analyzing the architecture and prompts of a hypothetical customer service bot inspired by real production applications. The [architecture and prompts](#architecture-and-prompts) section sets the stage, and the [analysis and optimizations](#analysis-and-optimizations) section will walk through the latency optimization process.
125
126You'll notice this example doesn't cover every single principle, much like
127 real-world use cases don't require applying every technique.
128
129### Architecture and prompts72### Architecture and prompts
130 73
131The following is the **initial architecture** for a hypothetical **customer service bot**. This is what we'll be making changes to.74A customer asks, “Is it still eligible for a return?” after discussing a pair of headphones. The support assistant makes three model calls in sequence. The first rewrites the question with the product name. The second decides whether to search. After retrieval, the third generates a reply plus internal fields for message count, sentiment, and tone. The customer sees nothing until the final call finishes.
132
133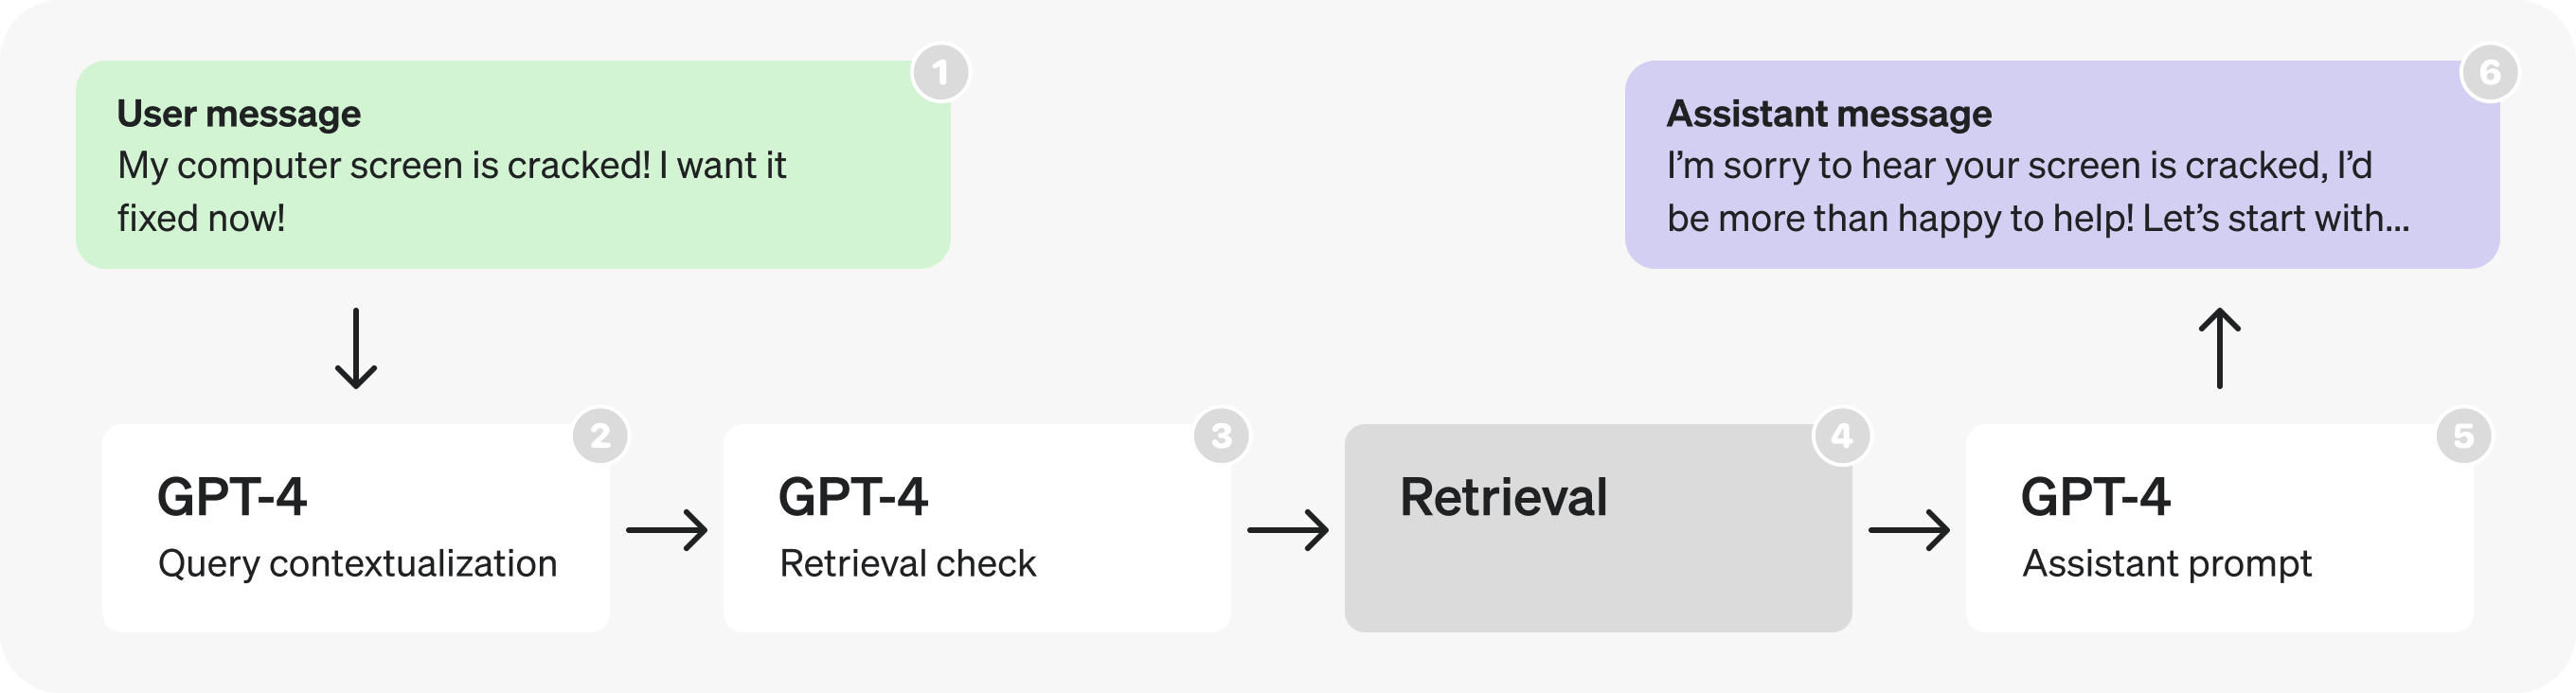
134
135At a high level, the diagram flow describes the following process:
136
1371. A user sends a message as part of an ongoing conversation.
1382. The last message is turned into a **self-contained query** (see examples in prompt).
1393. We determine whether or not **additional (retrieved) information is required** to respond to that query.
1404. **Retrieval** is performed, producing search results.
1415. The assistant **reasons** about the user's query and search results, and **produces a response**.
1426. The response is sent back to the user.
143
144Below are the prompts used in each part of the diagram. While they are still only hypothetical and simplified, they are written with the same structure and wording that you would find in a production application.
145
146Places where you see placeholders like "**[user input here]**" represent
147 dynamic portions, that would be replaced by actual data at runtime.
148
149
150
151#### Query contextualization prompt
152
153
154
155Re-writes user query to be a self-contained search query.
156
157```example-chat
158SYSTEM: Given the previous conversation, re-write the last user query so it contains
159all necessary context.
160
161# Example
162History: [{user: "What is your return policy?"},{assistant: "..."}]
163User Query: "How long does it cover?"
164Response: "How long does the return policy cover?"
165
166# Conversation
167[last 3 messages of conversation]
168
169# User Query
170[last user query]
171
172USER: [JSON-formatted input conversation here]
173```
174
175
176
177
178
179
180
181#### Retrieval check prompt
182
183
184Determines whether a query requires performing retrieval to respond.
185
186```example-chat
187SYSTEM: Given a user query, determine whether it requires doing a realtime lookup to
188respond to.
189
190# Examples
191User Query: "How can I return this item after 30 days?"
192Response: "true"
193
194User Query: "Thank you!"
195Response: "false"
196
197USER: [input user query here]
198```
199
200
201
202
203
204
205
206#### Assistant prompt
207
208
209Fills the fields of a JSON to reason through a pre-defined set of steps to produce a final response given a user conversation and relevant retrieved information.
210
211```example-chat
212SYSTEM: You are a helpful customer service bot.
213
214Use the result JSON to reason about each user query - use the retrieved context.
215
216# Example
217
218User: "My computer screen is cracked! I want it fixed now!!!"
219
220Assistant Response:
221{
222 "message_is_conversation_continuation": "True",
223 "number_of_messages_in_conversation_so_far": "1",
224 "user_sentiment": "Aggravated",
225 "query_type": "Hardware Issue",
226 "response_tone": "Validating and solution-oriented",
227 "response_requirements": "Propose options for repair or replacement.",
228 "user_requesting_to_talk_to_human": "False",
229 "enough_information_in_context": "True",
230 "response": "..."
231}
232
233USER: # Relevant Information
234` ` `
235[retrieved context]
236` ` `
237
238USER: [input user query here]
239```
240
241
242
243
244 75
245### Analysis and optimizations76### Analysis and optimizations
246 77
247#### Part 1: Looking at retrieval prompts78| Step | Change | What to measure |
248 79| ------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------- |
249Looking at the architecture, the first thing that stands out is the **consecutive GPT-4 calls** - these hint at a potential inefficiency, and can often be replaced by a single call or parallel calls.80| Route the question | Ask one model to decide whether to search and, if so, produce the standalone query. For this turn, the query is “headphones return policy.” An acknowledgment can skip retrieval. | Routing accuracy on both kinds of turns and time until retrieval starts. |
250 81| Fetch the evidence | Once the router identifies a return question, fetch the policy and the customer's order details concurrently if both inputs are available. | Elapsed time until both results are ready. |
251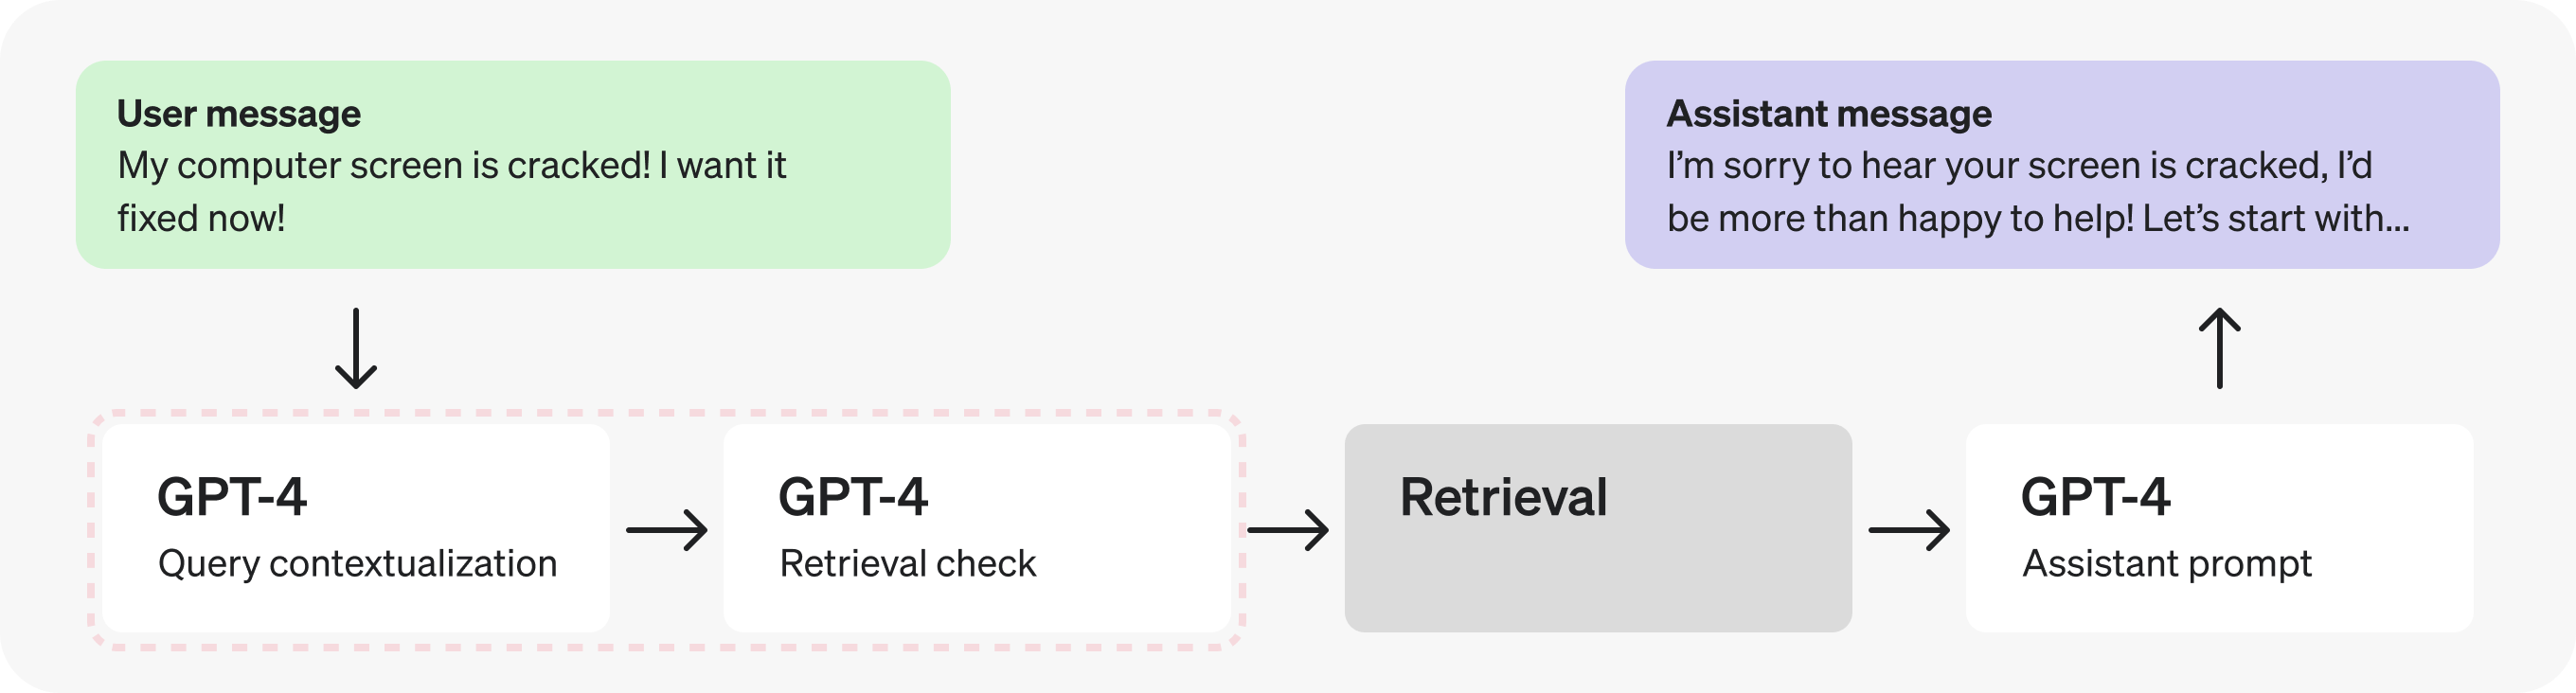82| Answer | Give the model the policy and order details, request only the customer-facing reply, and stream the text. If the policy or order lacks a fact needed to decide eligibility, ask for it. | Time to first visible text, time to the complete reply, and whether the eligibility decision is correct. |
252
253In this case, since the check for retrieval requires the contextualized query, let's **combine them into a single prompt** to [make fewer requests](#make-fewer-requests).
254
255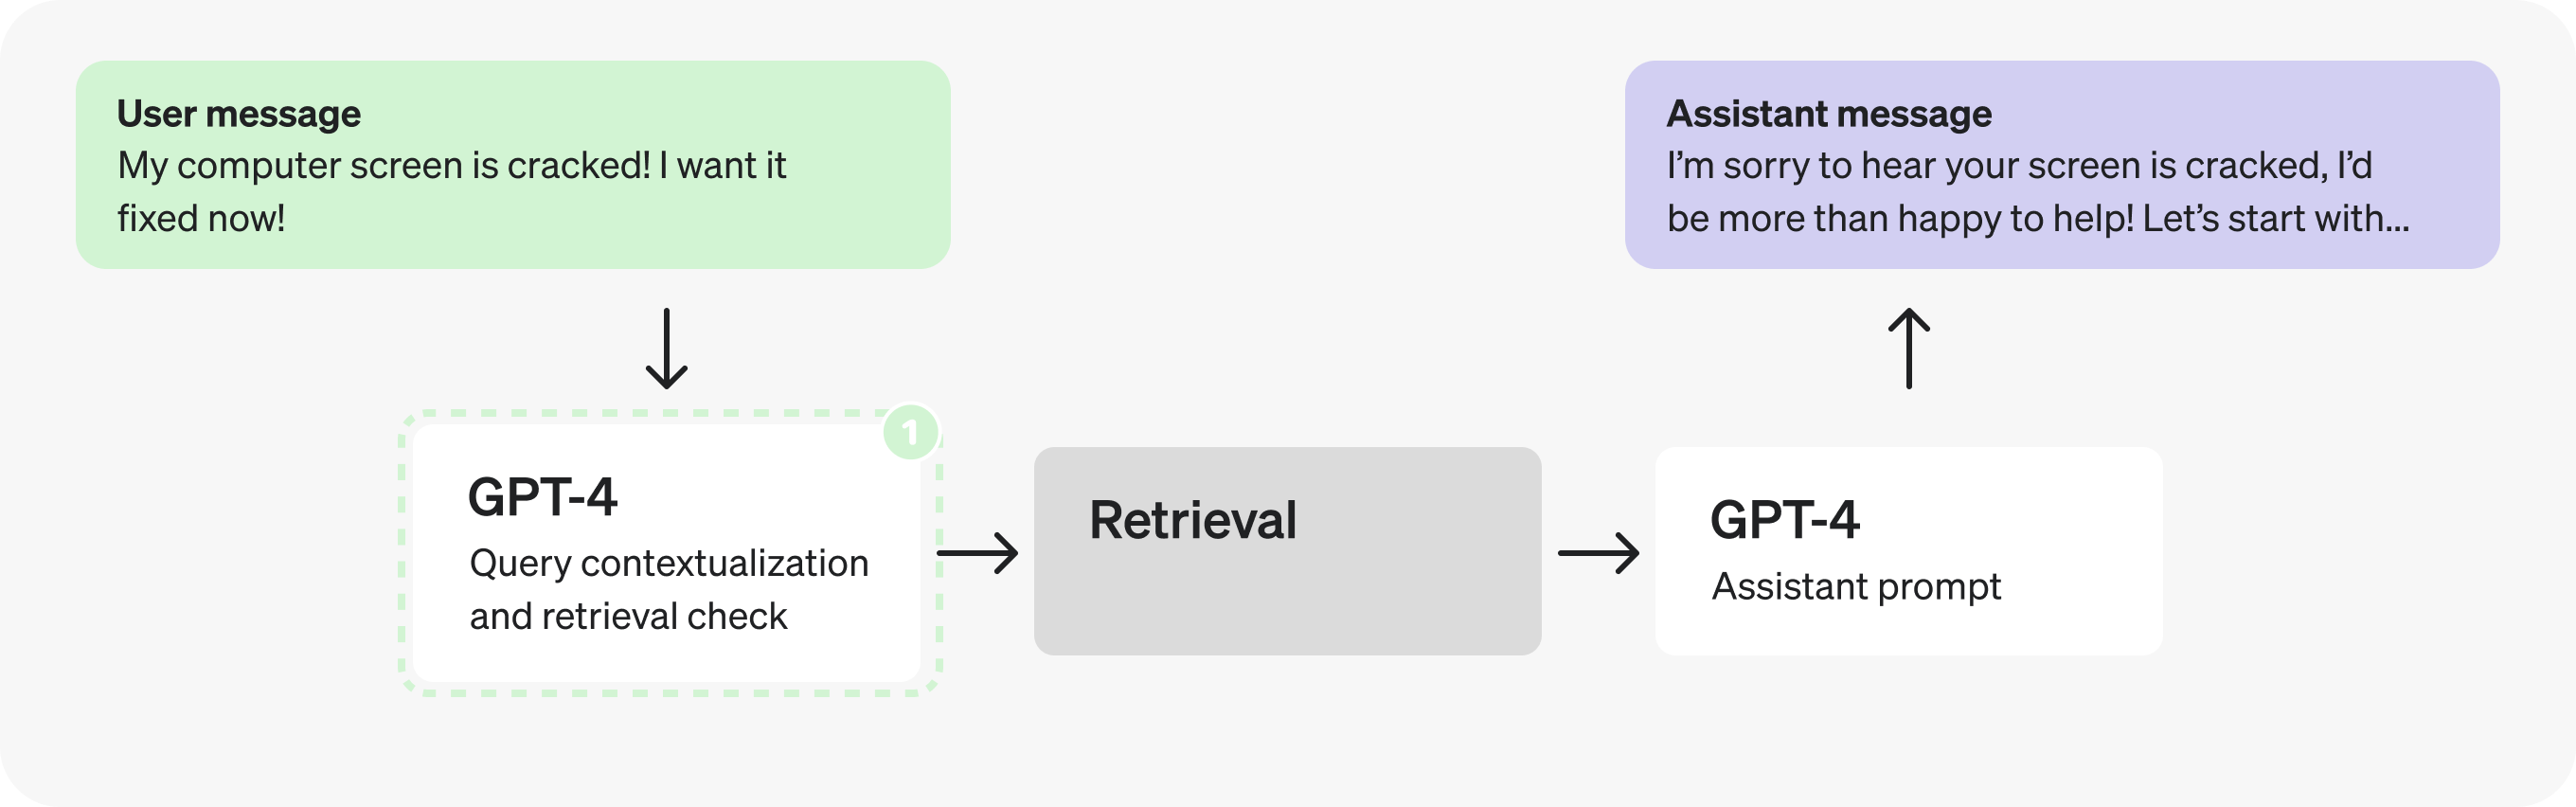
256
257
258
259##### Combined query contextualization and retrieval check prompt
260
261
262
263**What changed?** Before, we had one prompt to re-write the query and one to determine whether this requires doing a retrieval lookup. Now, this combined prompt does both. Specifically, notice the updated instruction in the first line of the prompt, and the updated output JSON:
264
265```javascript
266{
267 query: "[contextualized query]",
268 retrieval: "[true/false - whether retrieval is required]",
269};
270```
271
272```ruby
273require "json"
274
275combined_query = {
276 query: "[contextualized query]",
277 retrieval: "[true/false - whether retrieval is required]"
278}
279
280puts(JSON.generate(combined_query))
281```
282
283
284```example-chat
285SYSTEM: Given the previous conversation, re-write the last user query so it contains
286all necessary context. Then, determine whether the full request requires doing a
287realtime lookup to respond to.
288
289Respond in the following form:
290{
291 query:"[contextualized query]",
292 retrieval:"[true/false - whether retrieval is required]"
293}
294
295# Examples
296
297History: [{user: "What is your return policy?"},{assistant: "..."}]
298User Query: "How long does it cover?"
299Response: {query: "How long does the return policy cover?", retrieval: "true"}
300
301History: [{user: "How can I return this item after 30 days?"},{assistant: "..."}]
302User Query: "Thank you!"
303Response: {query: "Thank you!", retrieval: "false"}
304
305# Conversation
306[last 3 messages of conversation]
307
308# User Query
309[last user query]
310
311USER: [JSON-formatted input conversation here]
312```
313
314
315
316
317
318
319
320Actually, adding context and determining whether to retrieve are straightforward and well-defined tasks, so we can likely use a **smaller, fine-tuned model** instead. Switching to GPT-3.5 will let us [process tokens faster](#process-tokens-faster).
321
322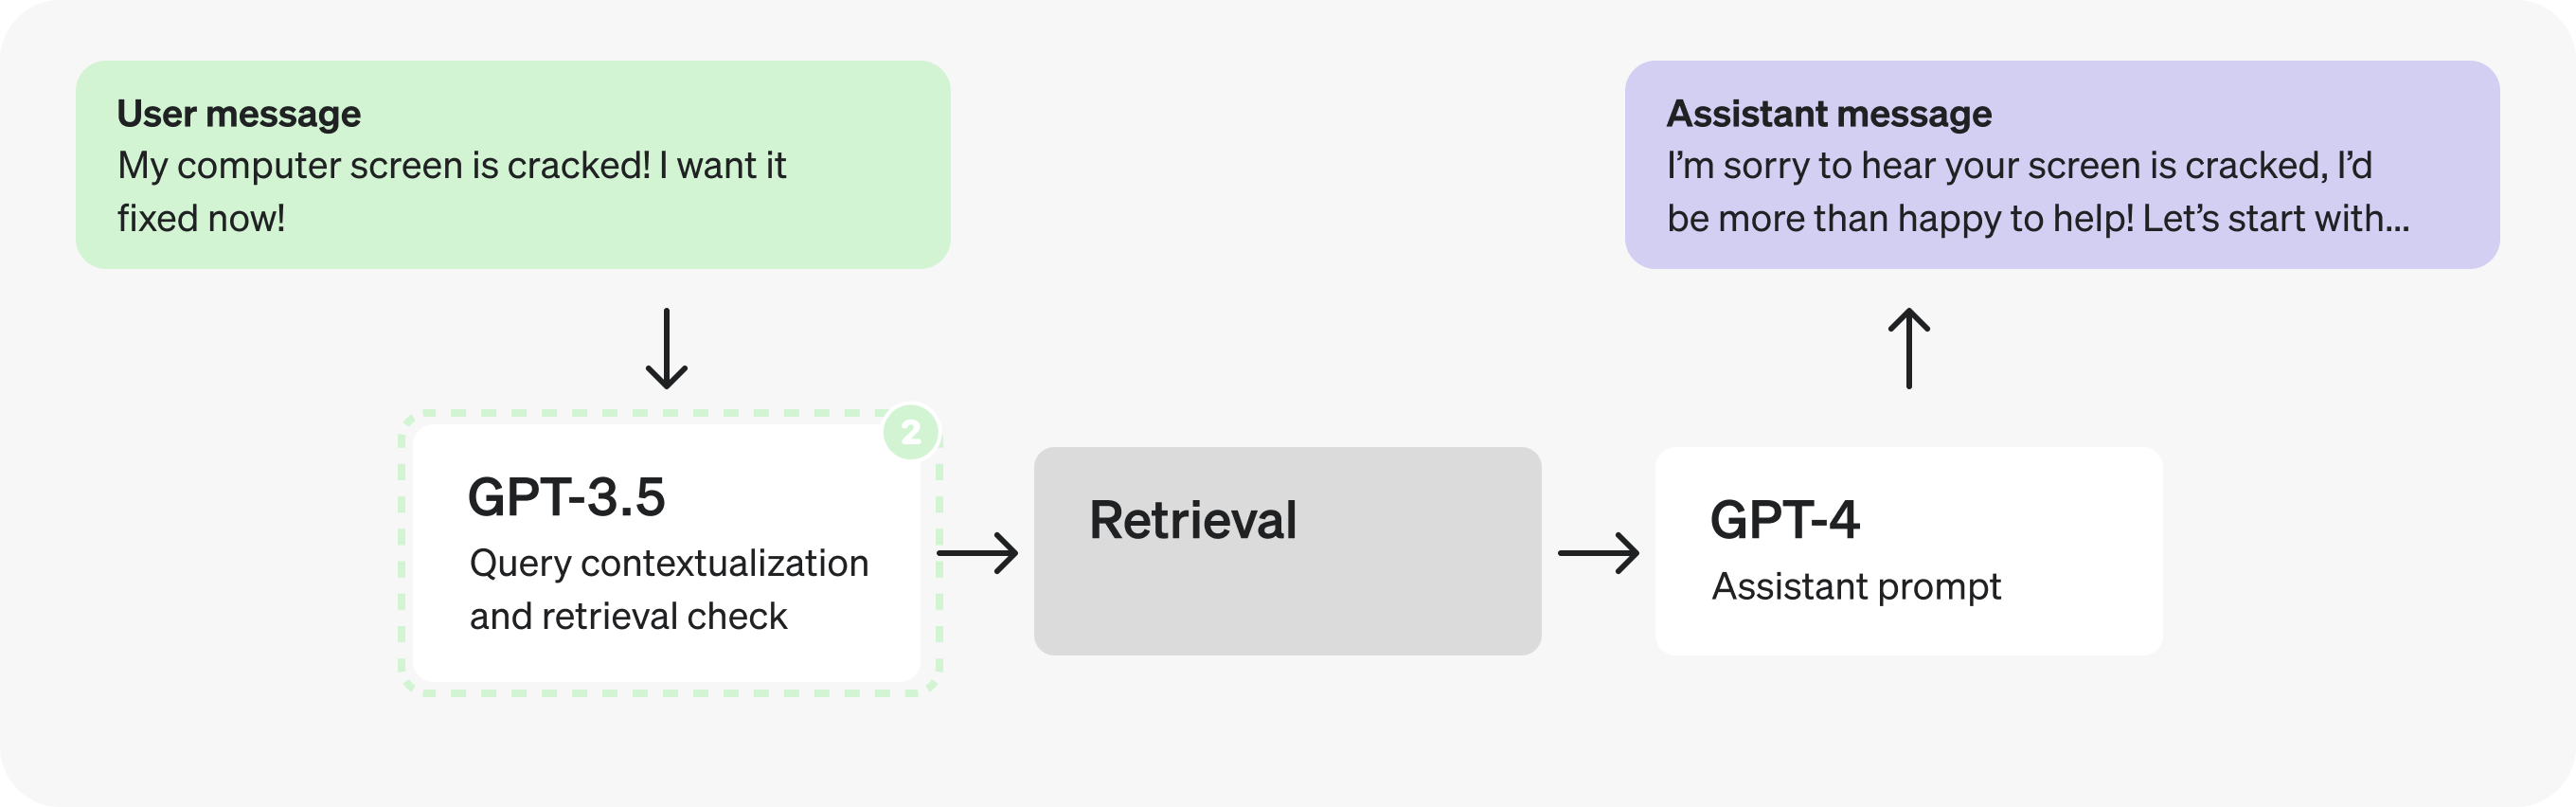
323
324#### Part 2: Analyzing the assistant prompt
325
326Let's now direct our attention to the Assistant prompt. There seem to be many distinct steps happening as it fills the JSON fields—this could indicate an opportunity to [parallelize](#parallelize).
327
328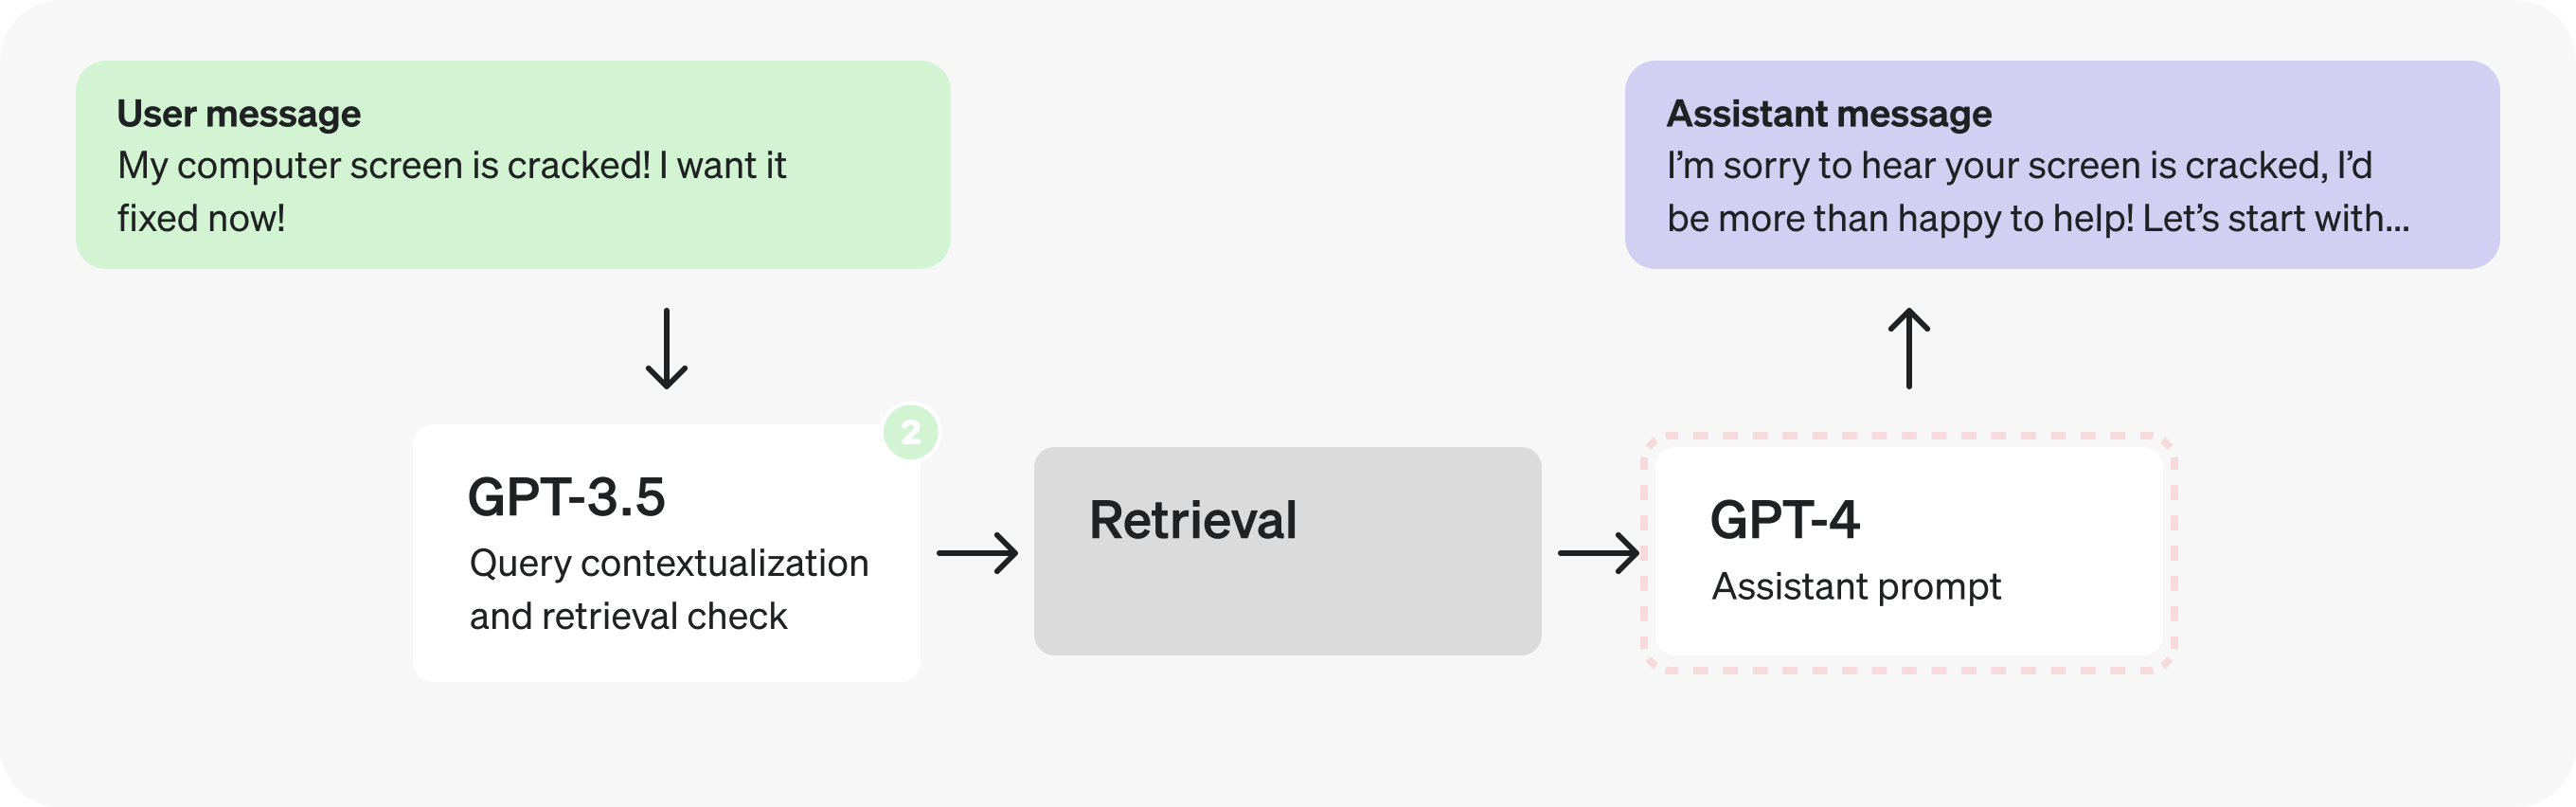
329
330However, let's pretend we have run some tests and discovered that splitting the reasoning steps in the JSON produces worse responses, so we need to explore different solutions.
331
332**Could we use a fine-tuned GPT-3.5 instead of GPT-4?** Maybe—but in general, open-ended responses from assistants are best left to GPT-4 so it can better handle a greater range of cases. That being said, looking at the reasoning steps themselves, they may not all require GPT-4-level reasoning to produce. Their well-defined, limited scope makes them **good potential candidates for fine-tuning**.
333
334```javascript
335{
336 message_is_conversation_continuation: "True", // <-
337 number_of_messages_in_conversation_so_far: "1", // <-
338 user_sentiment: "Aggravated", // <-
339 query_type: "Hardware Issue", // <-
340 response_tone: "Validating and solution-oriented", // <-
341 response_requirements: "Propose options for repair or replacement.", // <-
342 user_requesting_to_talk_to_human: "False", // <-
343 enough_information_in_context: "True", // <-
344 response: "...", // X -- benefits from GPT-4
345};
346```
347
348```ruby
349require "json"
350
351assistant_response = {
352 message_is_conversation_continuation: "True", # <-
353 number_of_messages_in_conversation_so_far: "1", # <-
354 user_sentiment: "Aggravated", # <-
355 query_type: "Hardware Issue", # <-
356 response_tone: "Validating and solution-oriented", # <-
357 response_requirements: "Propose options for repair or replacement.", # <-
358 user_requesting_to_talk_to_human: "False", # <-
359 enough_information_in_context: "True", # <-
360 response: "..." # X -- benefits from GPT-4
361}
362
363puts(JSON.generate(assistant_response))
364```
365
366
367This opens up the possibility of a trade-off. Do we keep this as a **single request entirely generated by GPT-4**, or **split it into two sequential requests** and use GPT-3.5 for all but the final response? We have a case of conflicting principles: the first option lets us [make fewer requests](#make-fewer-requests), but the second may let us [process tokens faster](#process-tokens-faster).
368
369As with many optimization tradeoffs, the answer will depend on the details. For example:
370
371- The proportion of tokens in the `response` vs the other fields.
372- The average latency decrease from processing most fields faster.
373- The average latency _increase_ from doing two requests instead of one.
374
375The conclusion will vary by case, and the best way to make the determination is by testing this with production examples. In this case, let's pretend the tests indicated it's favorable to split the prompt in two to [process tokens faster](#process-tokens-faster).
376
377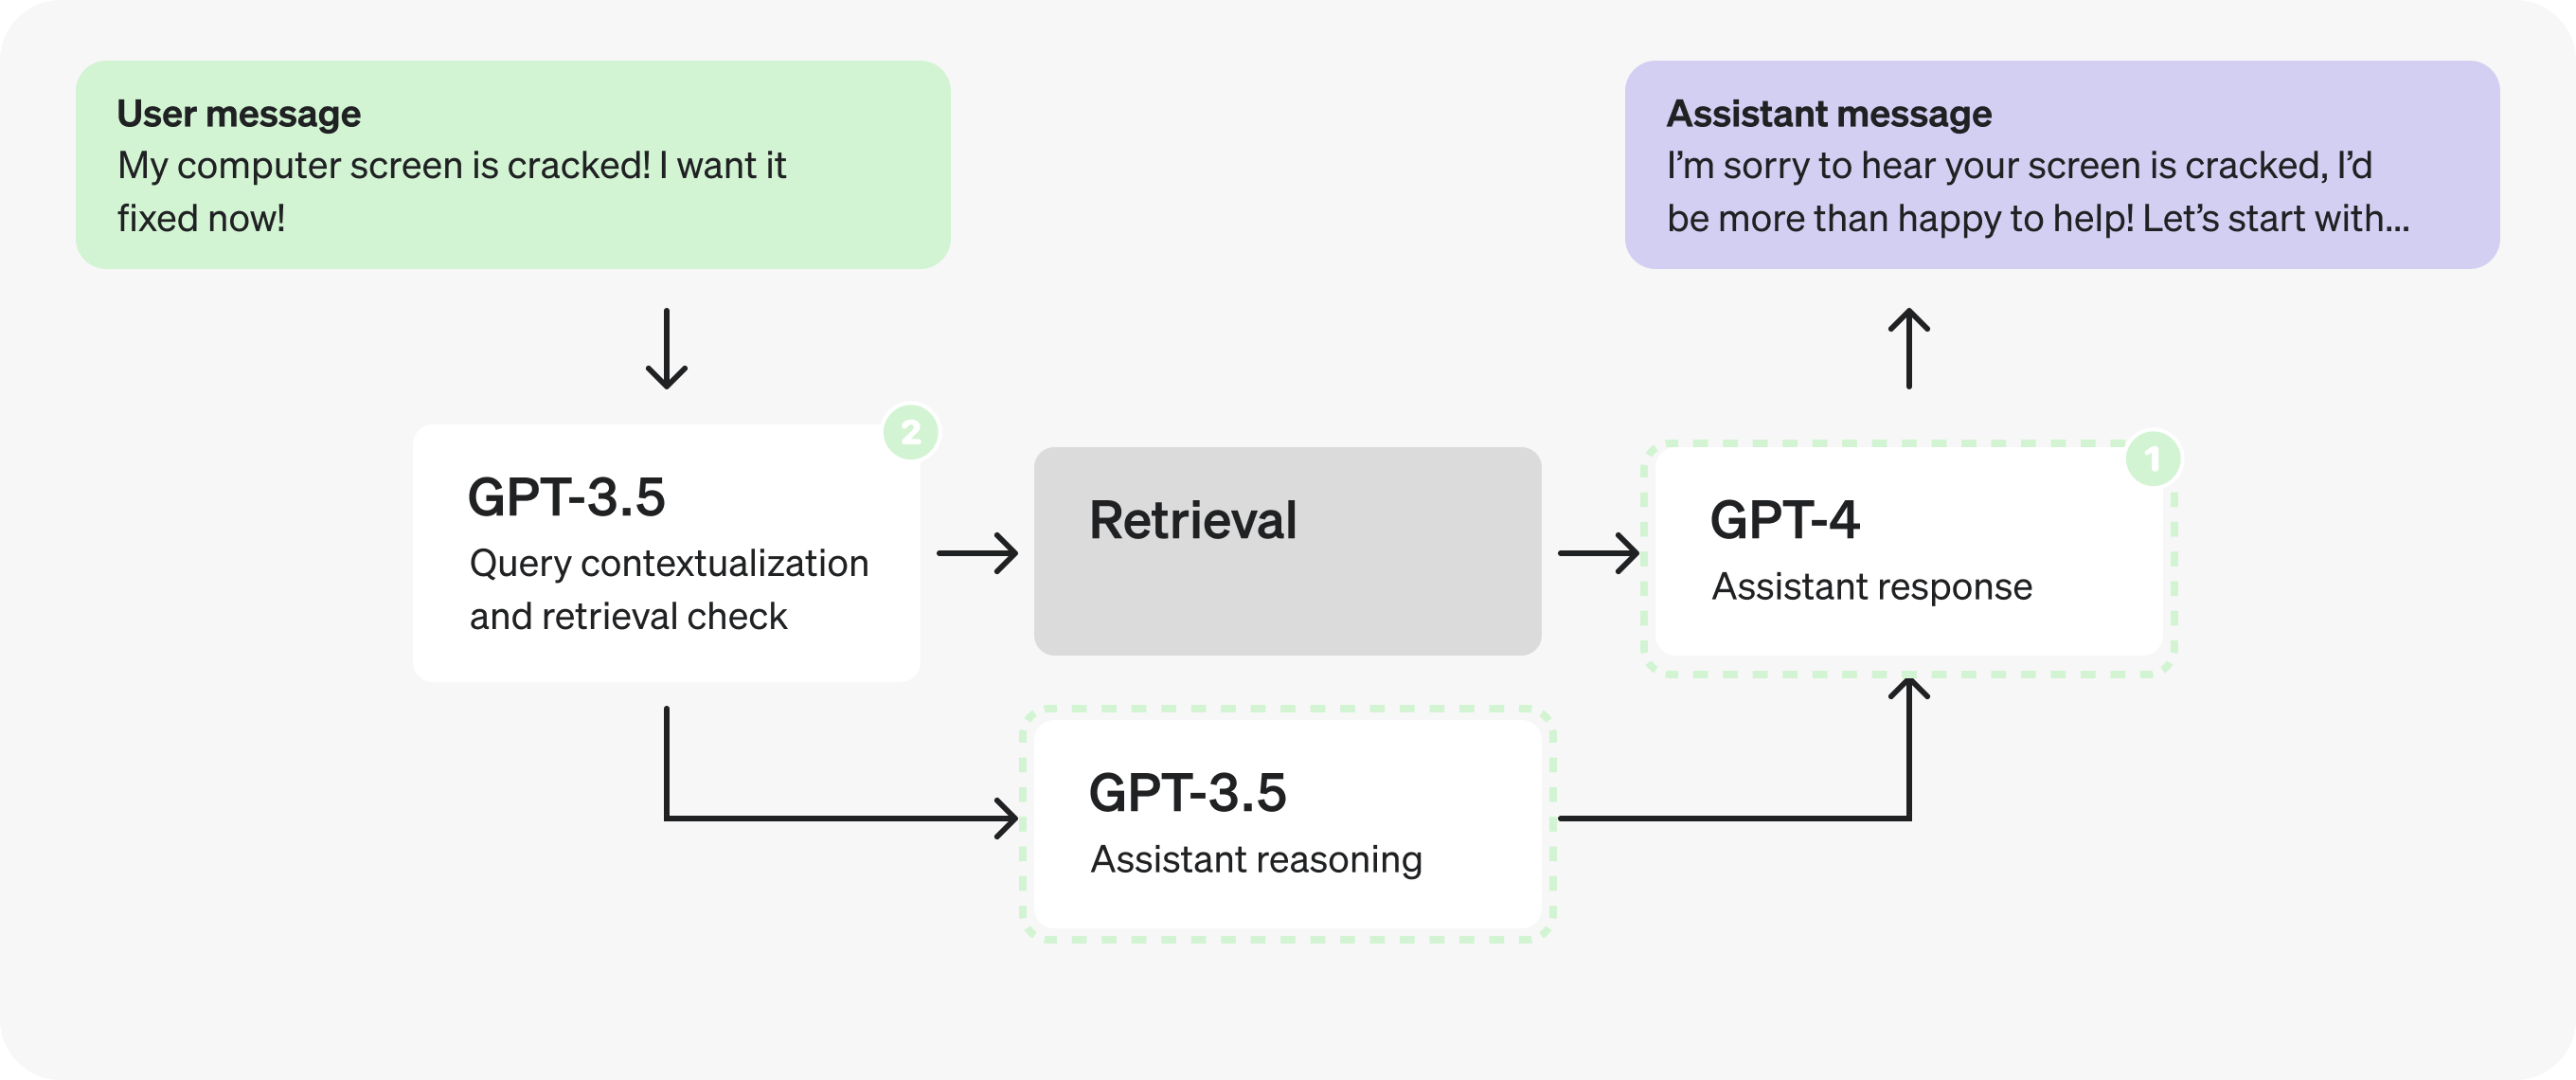
378
379**Note:** We'll be grouping `response` and `enough_information_in_context` together in the second prompt to avoid passing the retrieved context to both new prompts.
380
381
382
383##### Assistants prompt - reasoning
384
385
386
387This prompt will be passed to GPT-3.5 and can be fine-tuned on curated examples.
388
389**What changed?** The "enough_information_in_context" and "response" fields were removed, and the retrieval results are no longer loaded into this prompt.
390
391```example-chat
392SYSTEM: You are a helpful customer service bot.
393
394Based on the previous conversation, respond in a JSON to determine the required
395fields.
396
397# Example
398
399User: "My freaking computer screen is cracked!"
400
401Assistant Response:
402{
403 "message_is_conversation_continuation": "True",
404 "number_of_messages_in_conversation_so_far": "1",
405 "user_sentiment": "Aggravated",
406 "query_type": "Hardware Issue",
407 "response_tone": "Validating and solution-oriented",
408 "response_requirements": "Propose options for repair or replacement.",
409 "user_requesting_to_talk_to_human": "False",
410}
411```
412
413
414
415
416
417
418##### Assistants prompt - response
419
420
421
422This prompt will be processed by GPT-4 and will receive the reasoning steps determined in the prior prompt, as well as the results from retrieval.
423
424**What changed?** All steps were removed except for "enough_information_in_context" and "response". Additionally, the JSON we were previously filling in as output will be passed in to this prompt.
425
426```example-chat
427SYSTEM: You are a helpful customer service bot.
428
429Use the retrieved context, as well as these pre-classified fields, to respond to
430the user's query.
431
432# Reasoning Fields
433` ` `
434[reasoning json determined in previous GPT-3.5 call]
435` ` `
436
437# Example
438
439User: "My freaking computer screen is cracked!"
440
441Assistant Response:
442{
443 "enough_information_in_context": "True",
444 "response": "..."
445}
446
447USER: # Relevant Information
448` ` `
449[retrieved context]
450` ` `
451```
452
453
454
455
456
457
458
459
460In fact, now that the reasoning prompt does not depend on the retrieved context we can [parallelize](#parallelize) and fire it off at the same time as the retrieval prompts.
461
462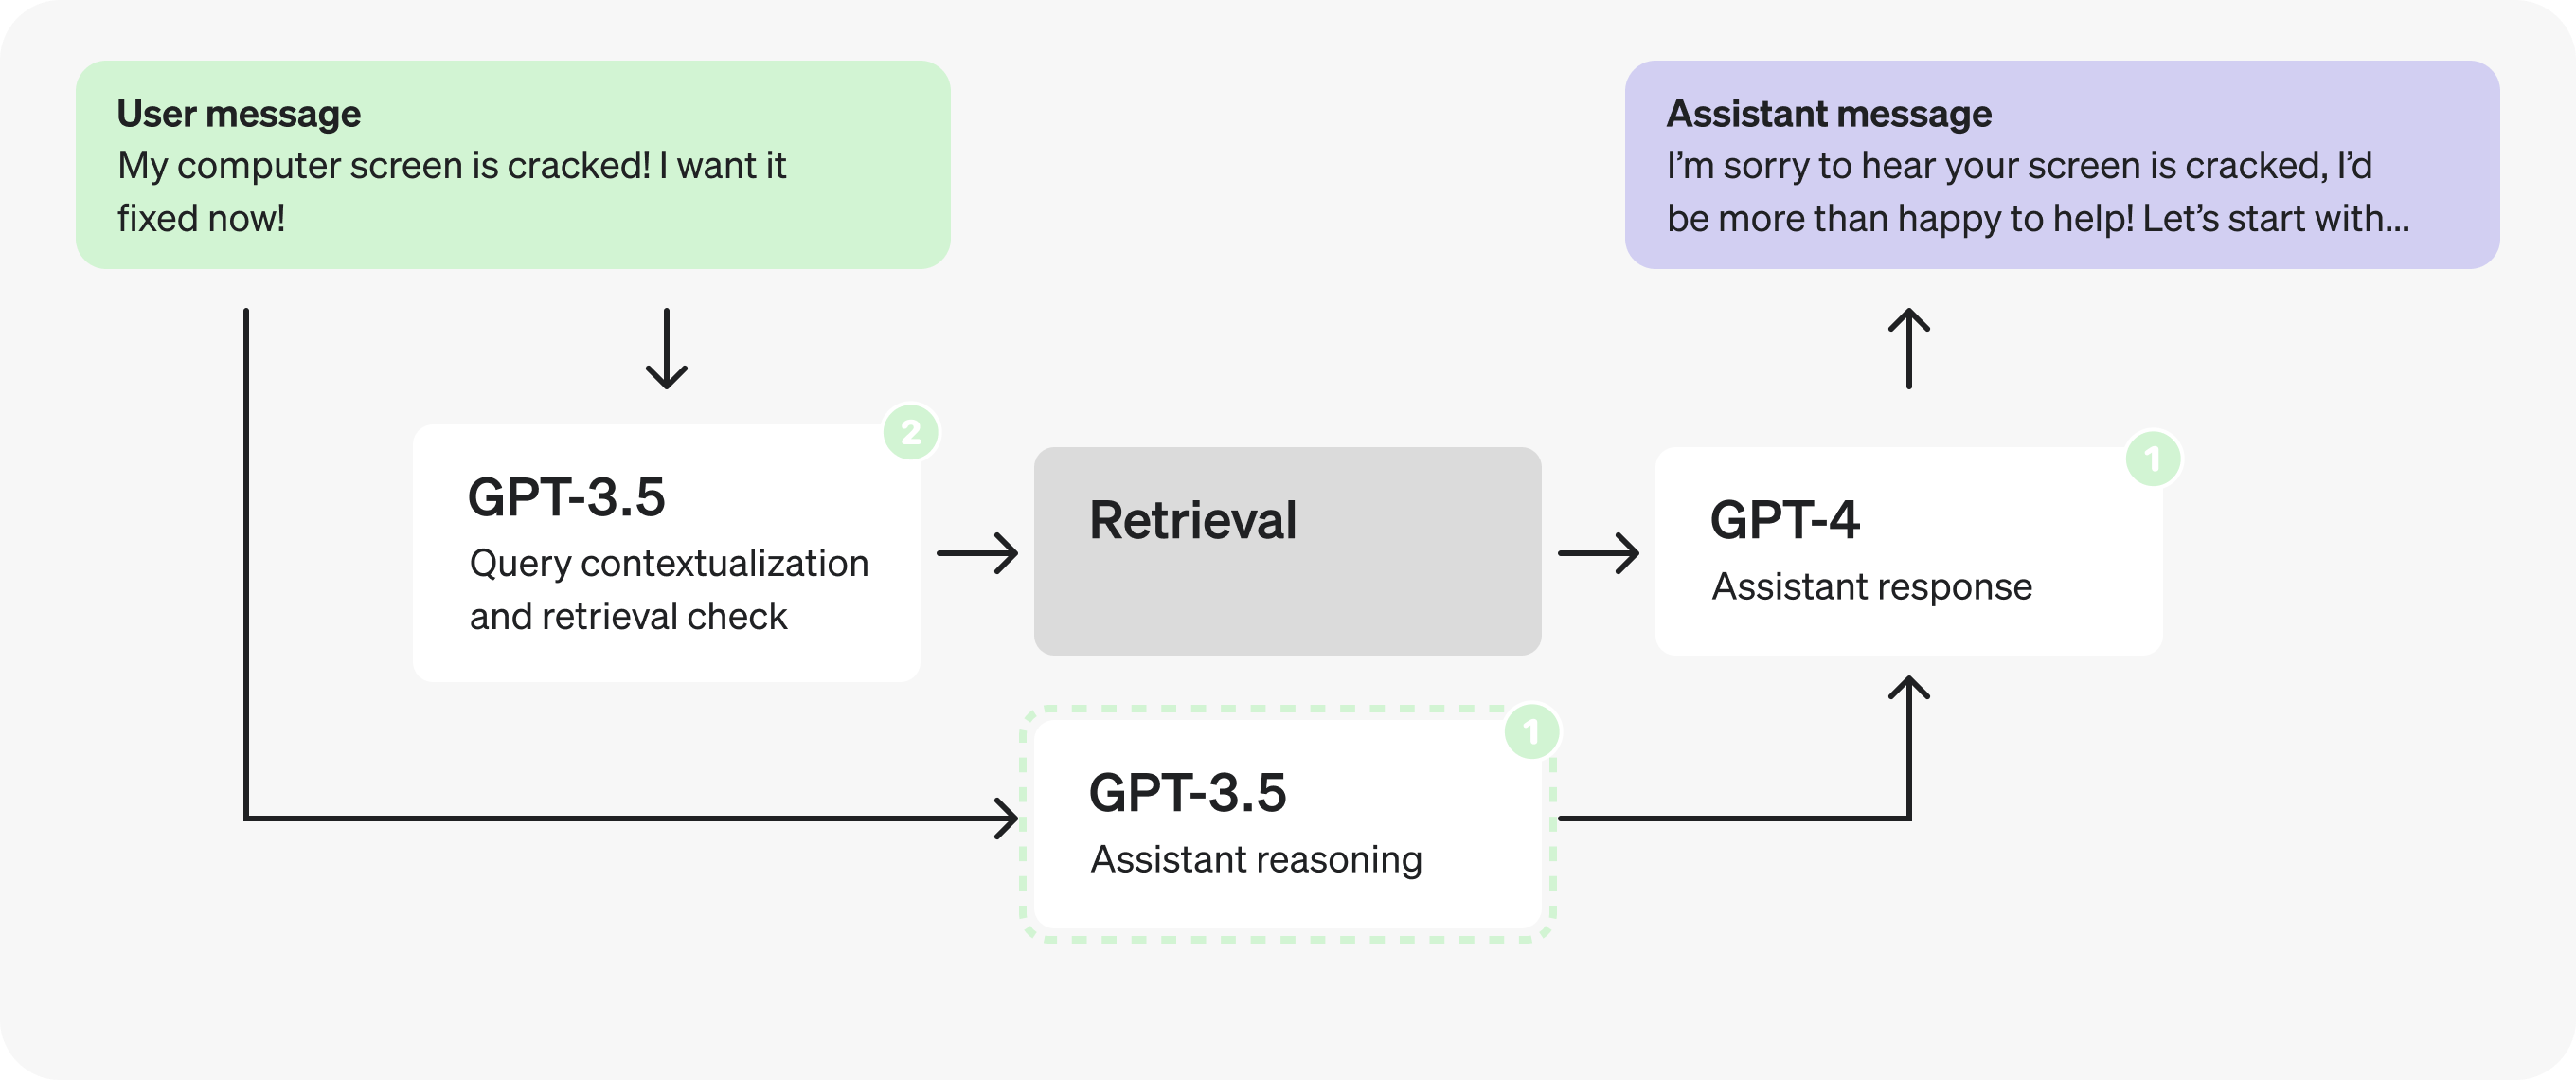
463
464#### Part 3: Optimizing the structured output
465
466Let's take another look at the reasoning prompt.
467
468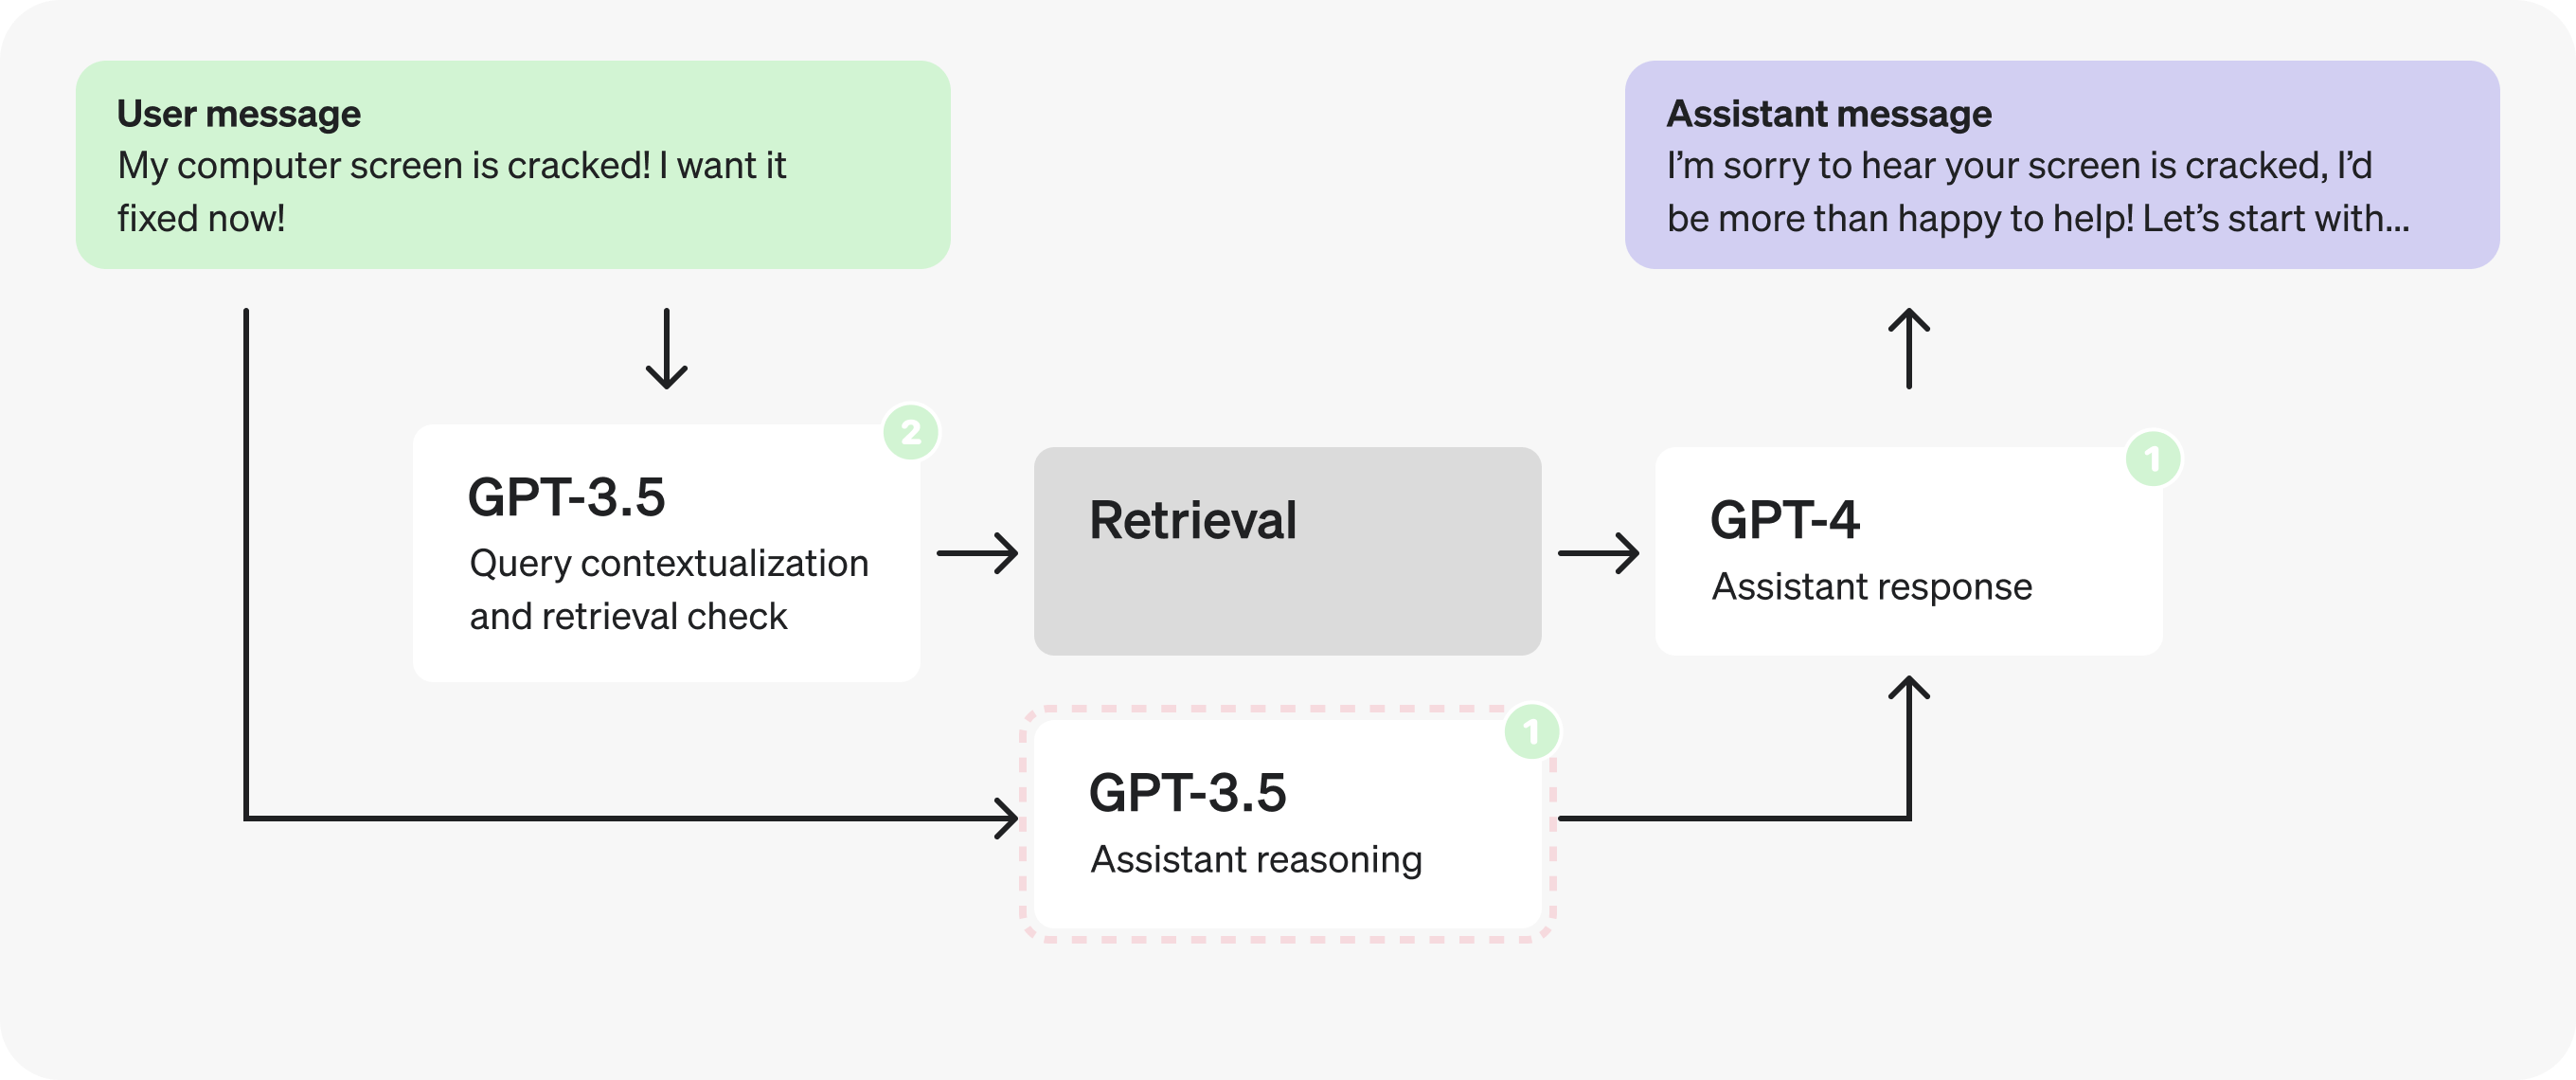
469
470Taking a closer look at the reasoning JSON you may notice the field names themselves are quite long.
471
472```javascript
473{
474 message_is_conversation_continuation: "True", // <-
475 number_of_messages_in_conversation_so_far: "1", // <-
476 user_sentiment: "Aggravated", // <-
477 query_type: "Hardware Issue", // <-
478 response_tone: "Validating and solution-oriented", // <-
479 response_requirements: "Propose options for repair or replacement.", // <-
480 user_requesting_to_talk_to_human: "False", // <-
481};
482```
483
484```ruby
485require "json"
486
487reasoning = {
488 message_is_conversation_continuation: "True", # <-
489 number_of_messages_in_conversation_so_far: "1", # <-
490 user_sentiment: "Aggravated", # <-
491 query_type: "Hardware Issue", # <-
492 response_tone: "Validating and solution-oriented", # <-
493 response_requirements: "Propose options for repair or replacement.", # <-
494 user_requesting_to_talk_to_human: "False" # <-
495}
496
497puts(JSON.generate(reasoning))
498```
499
500
501By making them shorter and moving explanations to the comments we can [generate fewer tokens](#generate-fewer-tokens).
502
503```javascript
504{
505 cont: "True", // whether last message is a continuation
506 n_msg: "1", // number of messages in the continued conversation
507 tone_in: "Aggravated", // sentiment of user query
508 type: "Hardware Issue", // type of the user query
509 tone_out: "Validating and solution-oriented", // desired tone for response
510 reqs: "Propose options for repair or replacement.", // response requirements
511 human: "False", // whether user is expressing want to talk to human
512};
513```
514
515```ruby
516require "json"
517
518reasoning = {
519 cont: "True", # whether last message is a continuation
520 n_msg: "1", # number of messages in the continued conversation
521 tone_in: "Aggravated", # sentiment of user query
522 type: "Hardware Issue", # type of the user query
523 tone_out: "Validating and solution-oriented", # desired tone for response
524 reqs: "Propose options for repair or replacement.", # response requirements
525 human: "False" # whether user wants to talk to a human
526}
527
528puts(JSON.generate(reasoning))
529```
530
531
532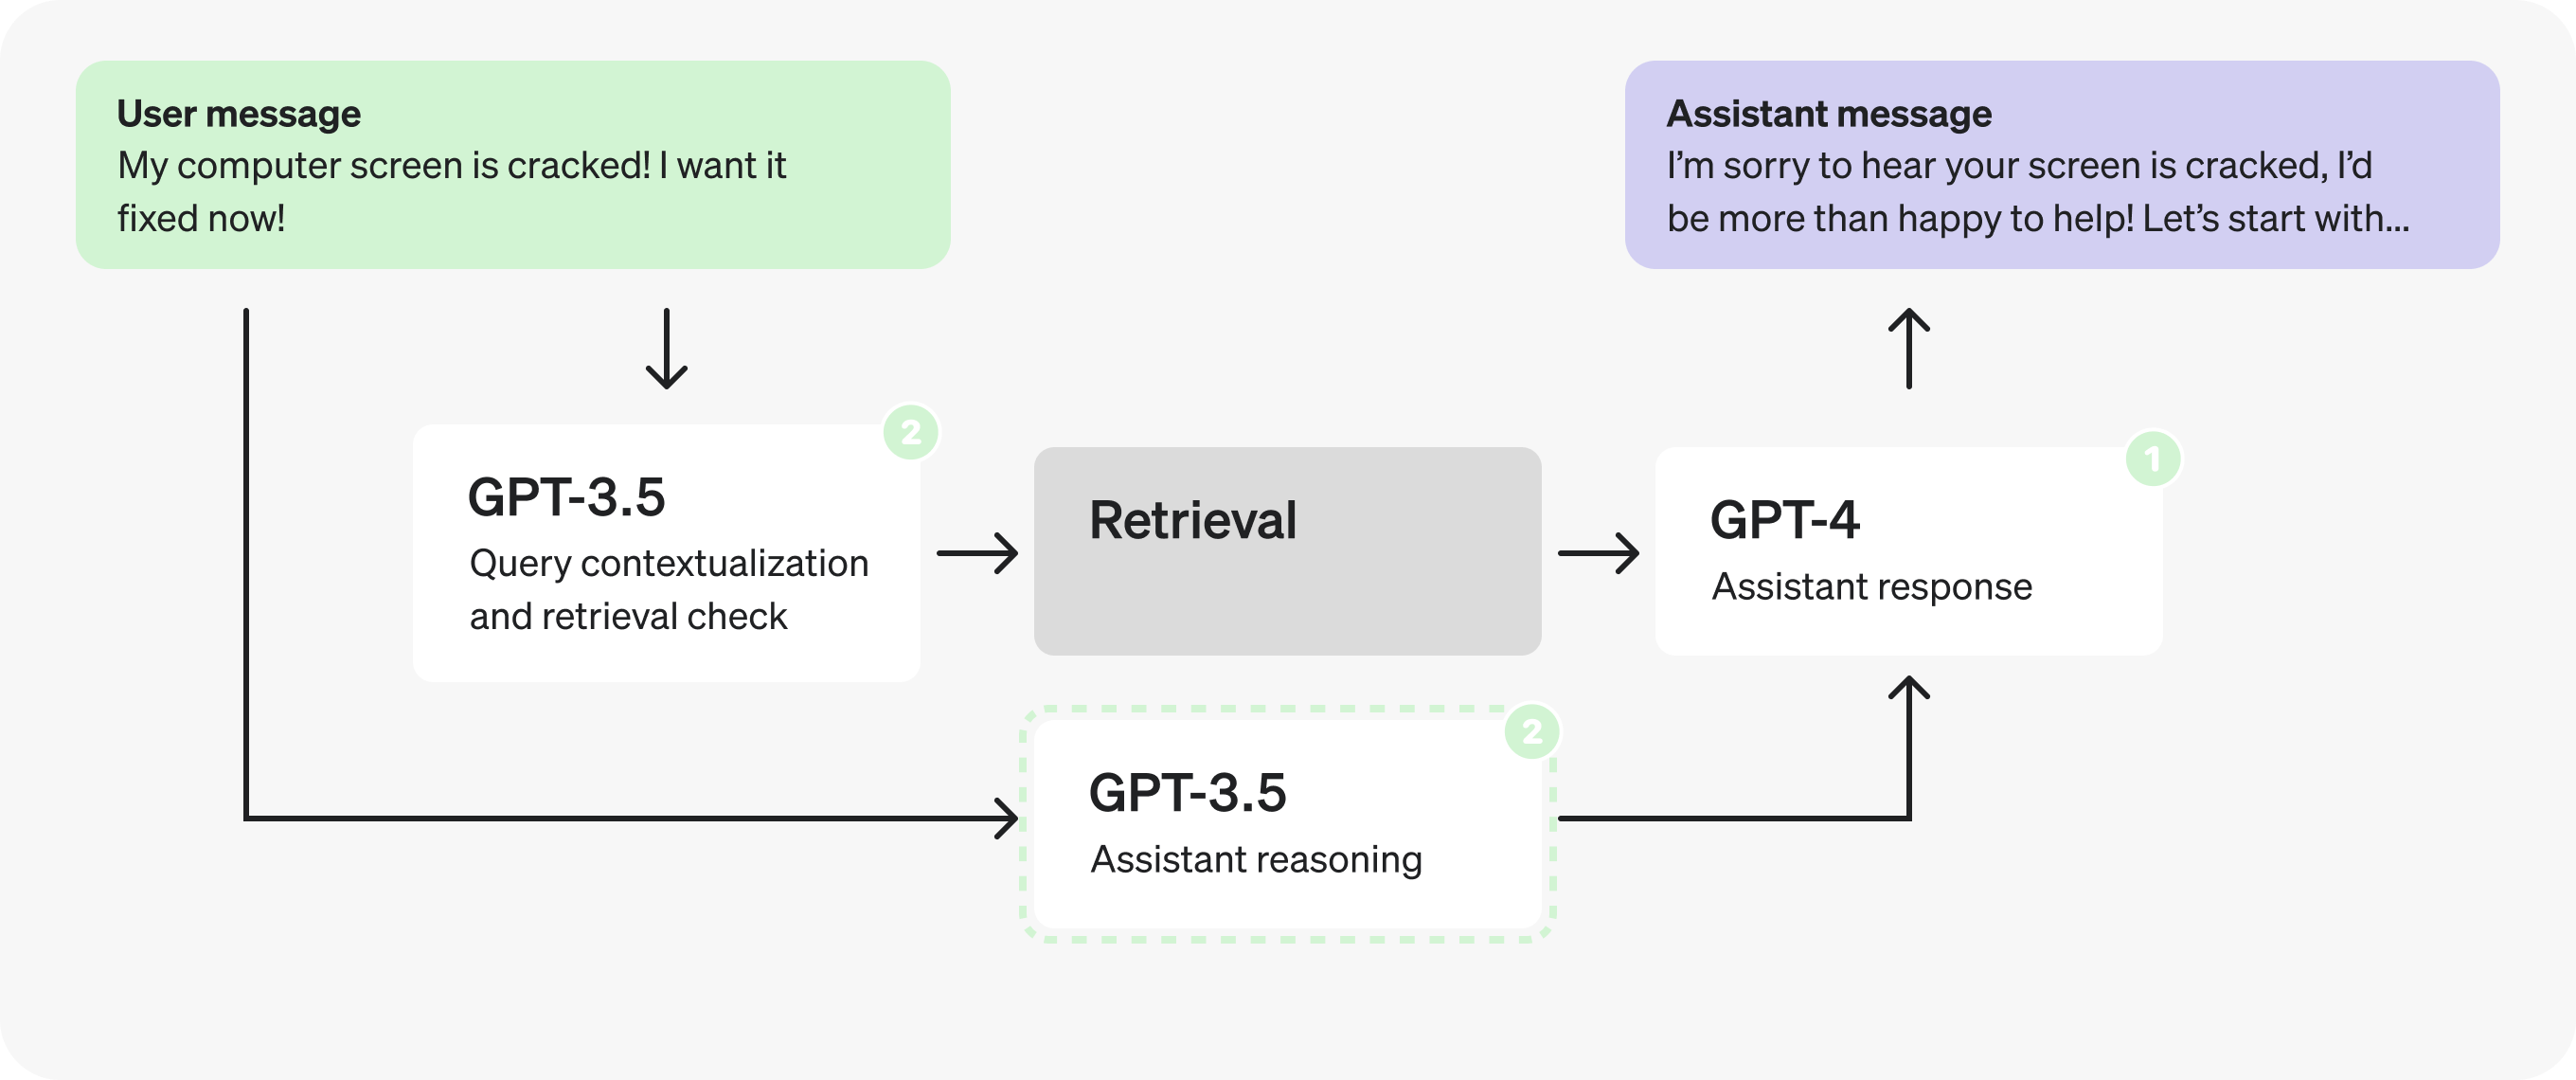
533
534This small change removed 19 output tokens. While with GPT-3.5 this may only result in a few millisecond improvement, with GPT-4 this could shave off up to a second.
535
536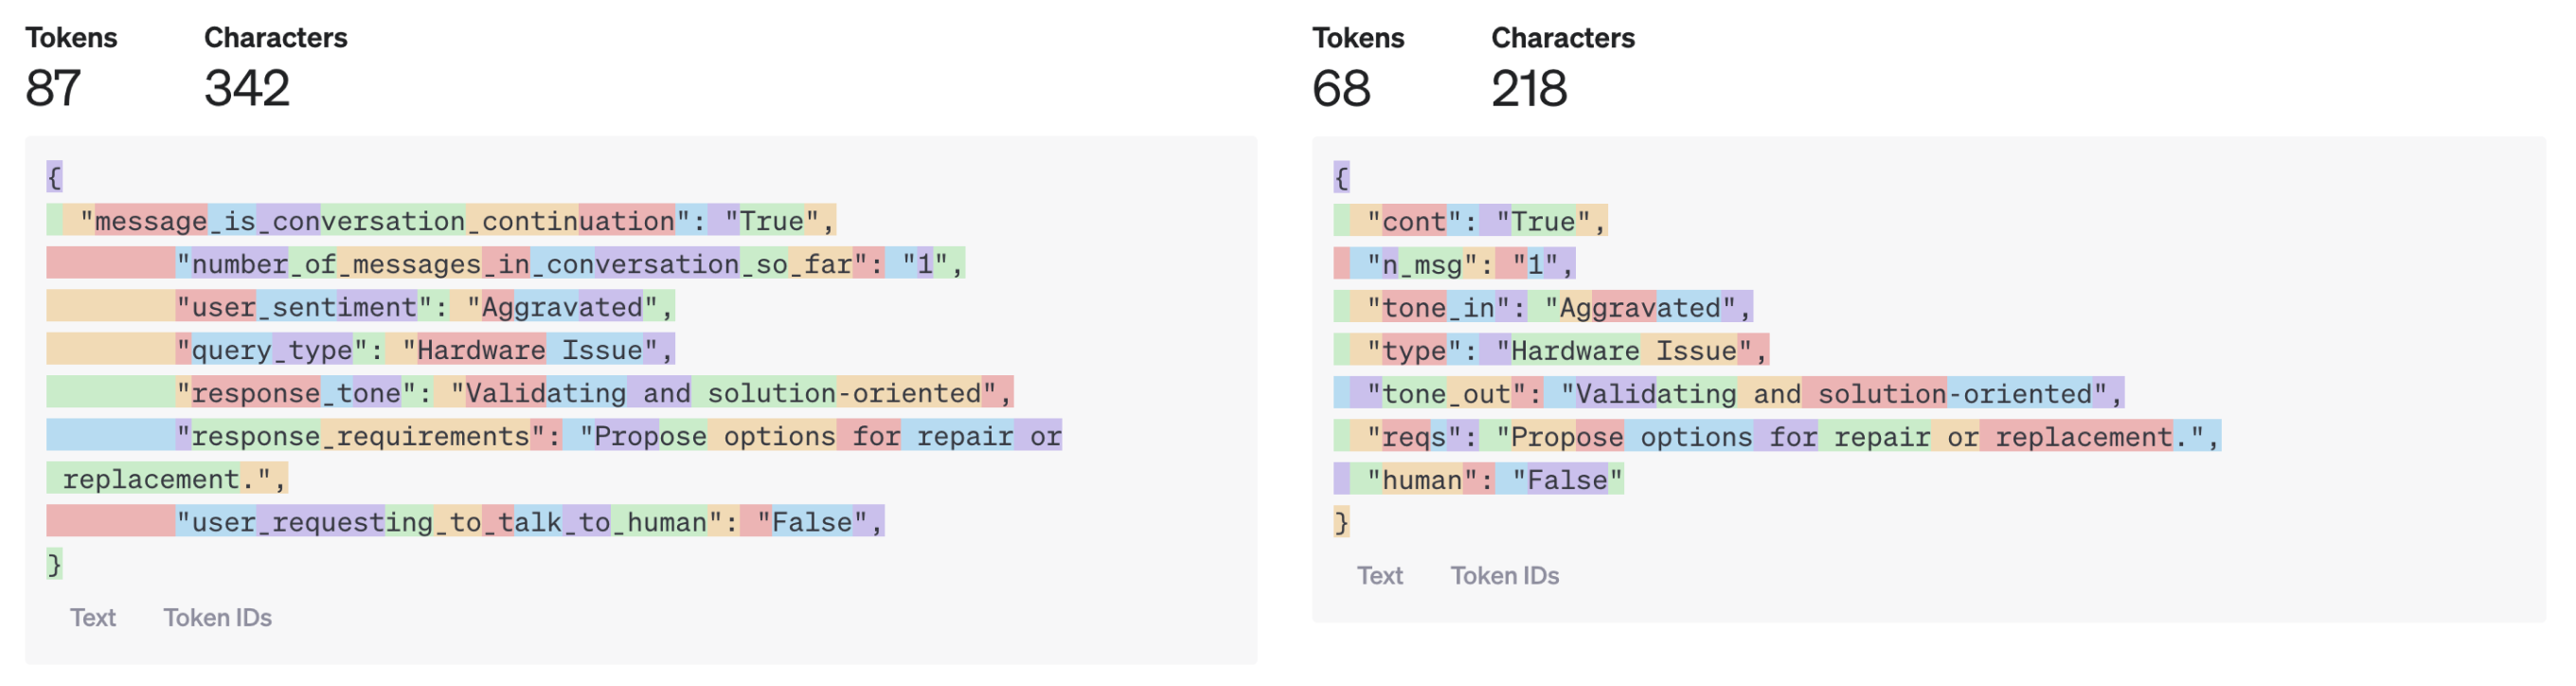
537
538You might imagine, however, how this can have quite a significant impact for larger model outputs.
539
540We could go further and use single characters for the JSON fields, or put everything in an array, but this may start to hurt our response quality. The best way to know, once again, is through testing.
541
542#### Example wrap-up
543
544Let's review the optimizations we implemented for the customer service bot example:
545
546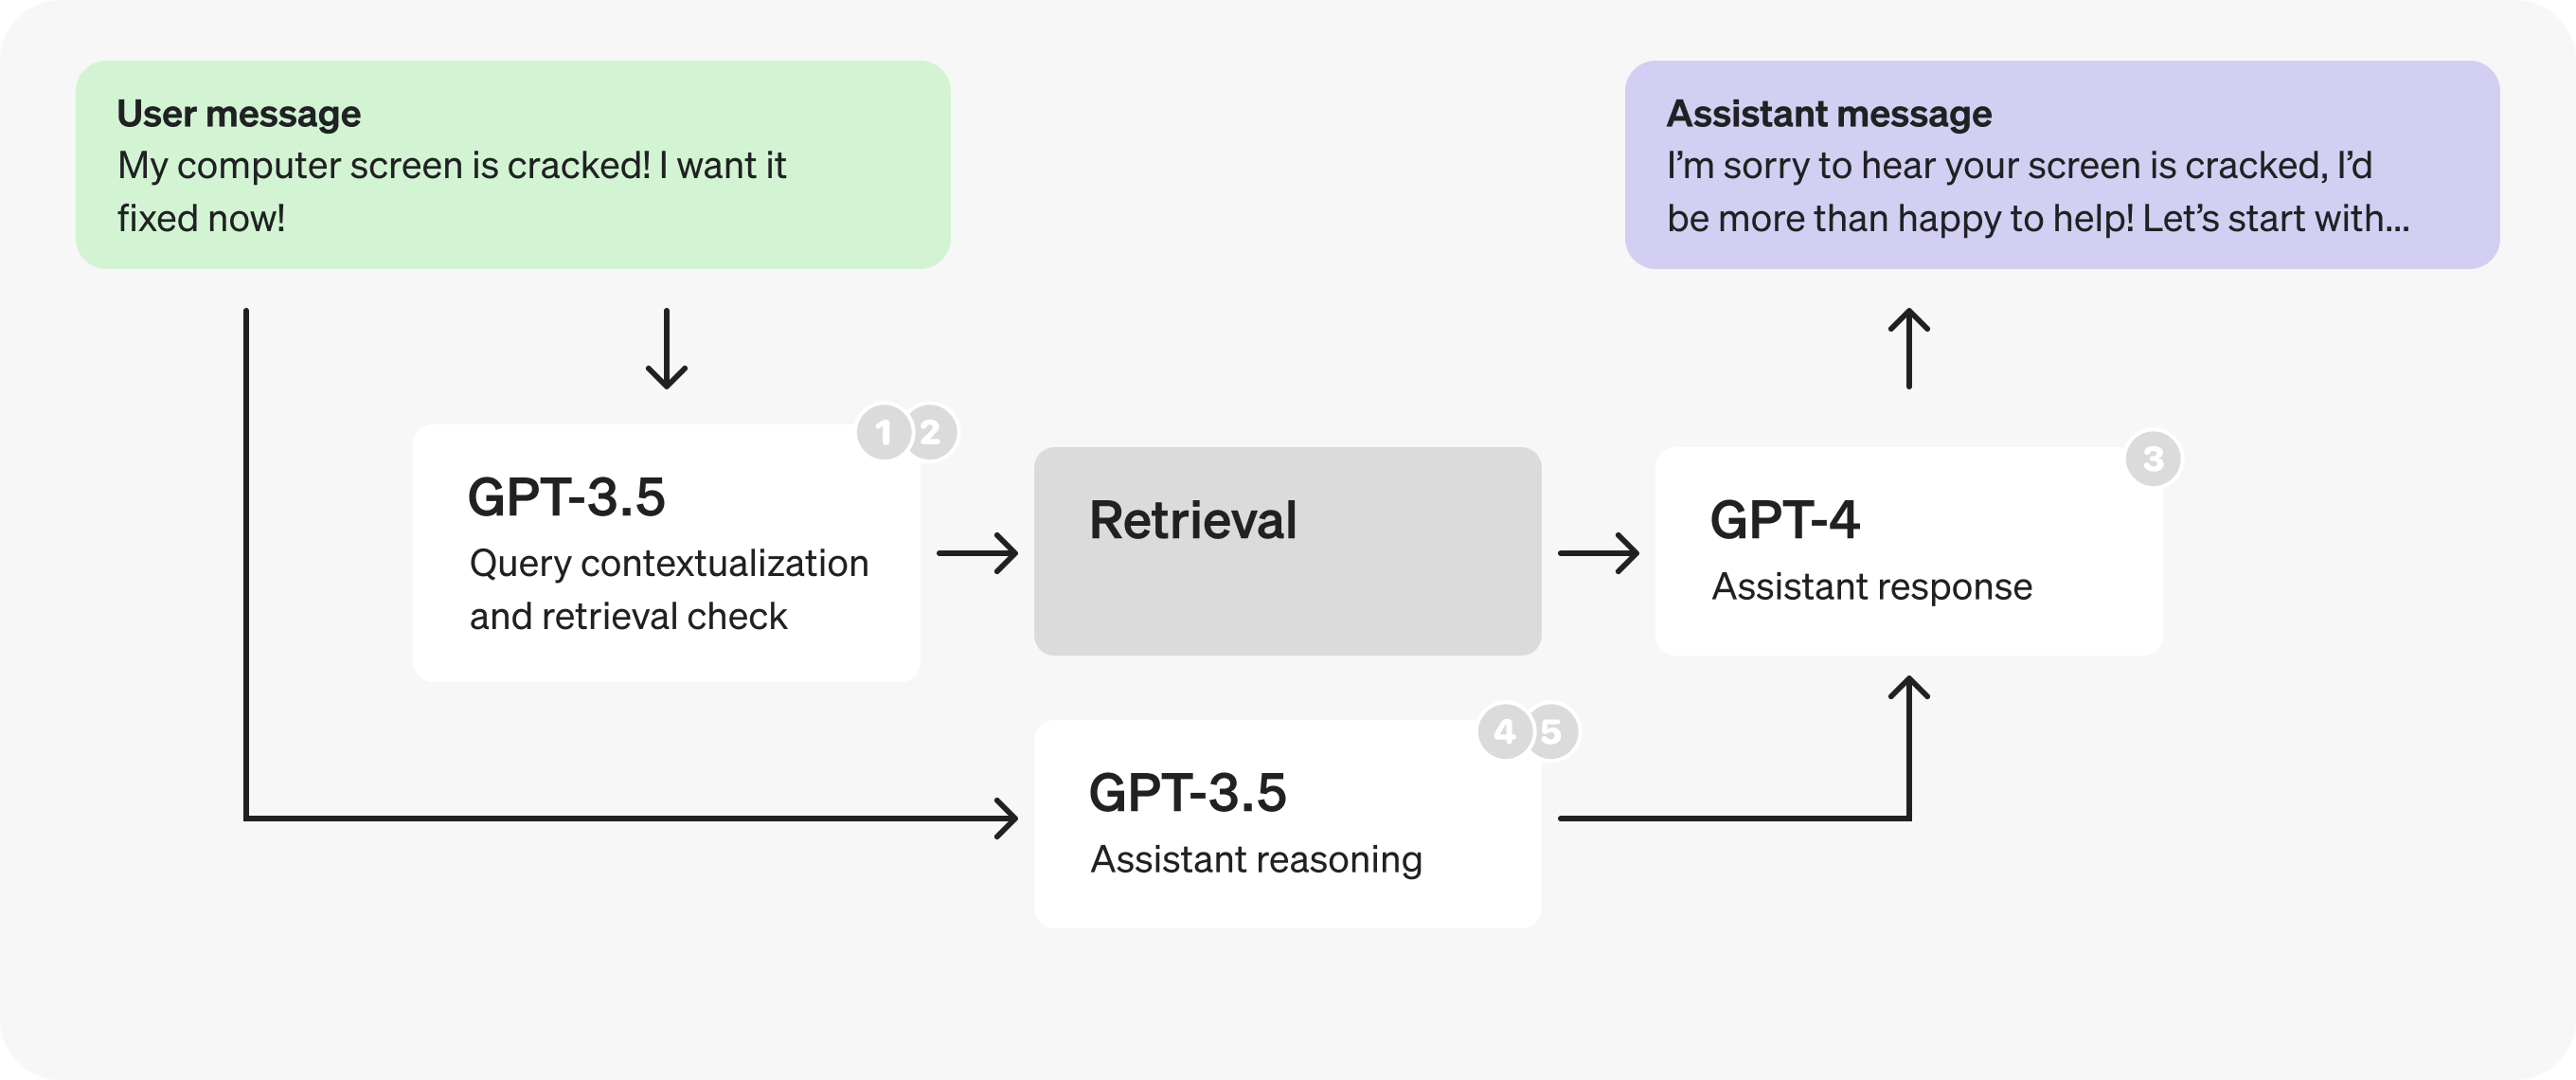
547 83
5481. **Combined** query contextualization and retrieval check steps to [make fewer requests](#make-fewer-requests).84On the return-question path, this removes one of three sequential model calls and overlaps two independent lookups. Replay the same support conversations before and after each change. Include ambiguous follow-ups and cases that need no lookup so a faster answer still sends customers to the right place.
5492. For the new prompt, **switched to a smaller, fine-tuned GPT-3.5** to [process tokens faster](#process-tokens-faster).
5503. Split the assistant prompt in two, **switching to a smaller, fine-tuned GPT-3.5** for the reasoning, again to [process tokens faster](#process-tokens-faster).
5514. [Parallelized](#parallelize) the retrieval checks and the reasoning steps.
5525. **Shortened reasoning field names** and moved comments into the prompt, to [generate fewer tokens](#generate-fewer-tokens).
