
enterprise/bedrock-through-litellm.md +0 −187 deleted
File Deleted View Diff
1# Bedrock through LiteLLM
2
3> For the complete documentation index, see [llms.txt](https://learn.chatgpt.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to the page URL.
4
5Use this page when your organization routes Codex to Amazon Bedrock through
6LiteLLM. If a LiteLLM gateway already exists, connect Codex first. Deploy LiteLLM
7only when your organization needs a new gateway.
8
9To use an existing gateway, start with [Connect to an existing
10 gateway](#connect-to-an-existing-gateway). To deploy LiteLLM on AWS, start
11 with [Prepare a gateway](#prepare-a-gateway). For access without a gateway,
12 see [Amazon Bedrock](https://learn.chatgpt.com/docs/amazon-bedrock).
13
14Other gateway products follow the same [gateway requirements](https://learn.chatgpt.com/docs/enterprise/gateway-compatibility)
15and [gateway connection flow](https://learn.chatgpt.com/docs/enterprise/connect-to-a-gateway).
16
17## Connect to an existing gateway
18
19Get these values from your gateway administrator:
20
21- The HTTPS base URL, such as `https://gateway.example.com/v1`.
22- The model alias that LiteLLM routes to an approved Bedrock model.
23- The provider ID to use in Codex configuration.
24- Native gateway OAuth settings, a scoped gateway API key, or an authentication
25 helper that returns the key.
26- Any model catalog distributed with your organization's configuration.
27
28Then complete the connection in this order:
29
301. Ask your gateway team to confirm that the gateway serves `POST /v1/responses`,
31 streams responses, preserves follow-up turns and tool calls, and routes the
32 approved alias. See [Gateway compatibility](https://learn.chatgpt.com/docs/enterprise/gateway-compatibility).
332. Follow [Connect to a gateway](https://learn.chatgpt.com/docs/enterprise/connect-to-a-gateway#configure-the-provider)
34 to configure the provider, model, and credential.
353. Verify the active provider and alias, send the short `gateway-ok` prompt from
36 the connection guide, and confirm that the LiteLLM record shows the expected
37 user and alias.
384. For organization-wide distribution, continue with [Roll out a gateway](https://learn.chatgpt.com/docs/enterprise/roll-out-a-gateway).
39
40Your gateway credential authenticates you to LiteLLM. The gateway manages its own Bedrock credentials; you don't need to copy those credentials to your workstation.
41
42If your gateway accepts OAuth access tokens, use [native gateway
43OAuth](https://learn.chatgpt.com/docs/enterprise/connect-to-a-gateway#use-native-gateway-oauth) for browser
44sign-in without ChatGPT sign-in or a credential helper. Confirm that your deployed
45gateway validates the token in the configured cookie or custom header. A LiteLLM
46API key alone doesn't enable this flow.
47
48## Prepare a gateway
49
50Use this section only when you need to create a LiteLLM gateway before connecting
51Codex.
52
53### Before you deploy
54
55Confirm that you have:
56
57- Permission to deploy the approved LiteLLM architecture in your AWS environment.
58- Bedrock access to the models or inference profiles you will route.
59- A reviewed LiteLLM image and deployment pattern.
60- A trusted HTTPS host name and certificate.
61- A restricted client network range.
62
63For the Runtime example below, the gateway's AWS identity needs `bedrock:InvokeModel` for the selected inference profile and the account's default project. See AWS's [GPT-6 Sol setup instructions](https://docs.aws.amazon.com/bedrock/latest/userguide/model-card-openai-gpt-6-sol.html) for the required permissions.
64
65### Architecture
66
67The deployment keeps LiteLLM between Codex and Bedrock, with HTTPS at the client
68boundary. The load balancer and LiteLLM are inside your organization's gateway
69boundary; the provider credential stays on the gateway.
70
71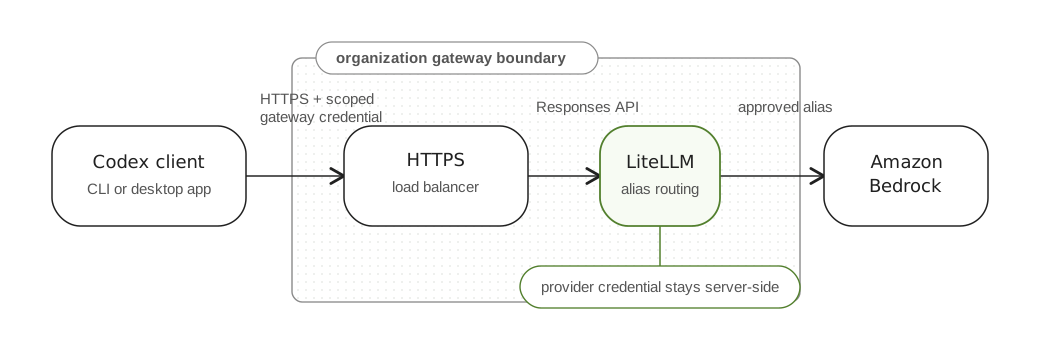
72
73Restrict inbound access to approved clients, keep database and cache ports private, and grant the gateway only the Bedrock permissions it needs. Pin the deployed image by digest so that a restart doesn't silently change the implementation.
74
75Prompts, source excerpts, and tool results pass through the gateway and may enter its logs. Decide retention, access, and redaction before enabling request logging. MCP servers and plugins have separate connections and authentication; this gateway configuration doesn't configure them.
76
77### Deployment checkpoints
78
79Complete these checkpoints in order before handing the gateway to developers:
80
81| Checkpoint | Output |
82| -------------------------------------------------------------- | ----------------------------------------------------------------------------------------- |
83| Deploy the proxy with private database and cache dependencies. | A stable HTTPS base URL ending in `/v1`, with gateway-managed Bedrock authentication. |
84| Configure a model route and its matching client catalog. | A stable Codex-facing alias mapped to the intended Bedrock target. |
85| Verify Responses support. | A streamed `POST /v1/responses` response ending with `response.completed`. |
86| Issue a test credential. | A per-user virtual key restricted to the alias, with expiration, budget, and rate limits. |
87| Connect one developer. | Codex provider configuration and a verified short prompt through the gateway. |
88
89The sections below cover each checkpoint. For production rollout, also test
90follow-up turns, tools, and credential revocation.
91
92### Choose the Bedrock route
93
94The LiteLLM upstream route determines the Bedrock endpoint, model identifier, and authentication method. Keep these choices together when you deploy or change the gateway.
95
96Use Bedrock Runtime for new configurations. The example below uses its OpenAI-compatible Responses endpoint.
97
98Hosted web search isn't available on Bedrock Runtime. If you need it, use
99 Mantle and confirm that your gateway preserves the tool request and response.
100
101See LiteLLM's [Bedrock Mantle integration](https://docs.litellm.ai/docs/providers/bedrock_mantle) for the alternative route.
102
103For an AWS deployment example, use the pinned [LiteLLM on ECS reference](https://github.com/openai-on-aws/guidance-codex/blob/eb04fe0/docs/QUICKSTART_LLM_GATEWAY_LITELLM.md). That implementation uses Bedrock Runtime and refreshes authentication from the ECS task role. Follow its deployment and authentication steps together, and review its production requirements against your networking, TLS, logging, and resource-retention policies.
104
105Whichever route you choose, verify the deployed combination of gateway version, upstream endpoint, and model against [Gateway compatibility](https://learn.chatgpt.com/docs/enterprise/gateway-compatibility). An upstream model appearing in the gateway's model list doesn't establish that its streaming, continuation, and tool behavior work with Codex.
106
107### Configure a Runtime model route
108
109Map a stable Codex-facing alias to the approved upstream model. Confirm access in your AWS account and Region before using this Runtime example.
110
111```yaml
112model_list:
113 - model_name: company-coding-model
114 litellm_params:
115 model: openai/global.openai.gpt-6-sol
116 api_key: os.environ/AWS_BEARER_TOKEN_BEDROCK
117 api_base: https://bedrock-runtime.us-east-1.amazonaws.com/openai/v1
118```
119
120Supply a valid Bedrock API key as `AWS_BEARER_TOKEN_BEDROCK` through your secret-management system. For a short-lived key, issue a replacement before it expires, update the gateway process environment, and restart or redeploy the workers that use it. The ECS reference instead refreshes credentials in-process from its task role; use its configuration and entrypoint together.
121
122The `openai/` prefix selects LiteLLM's OpenAI-compatible adapter; the configured `api_base` sends requests to Bedrock Runtime. The Global inference profile can route requests outside the source Region. Choose a profile and Region that meet your AWS permissions and data-residency requirements, and replace both values as needed.
123
124The client sends `company-coding-model`; LiteLLM uses the configured upstream route. This custom alias requires the matching client catalog described next. A generic gateway does not inherit the built-in Bedrock provider's metadata adjustments.
125
126### Prepare the client catalog
127
128For this GPT-6 Sol/Runtime example with Codex 0.158.0, start with the complete `gpt-6-sol` entry from that version's [model catalog](https://github.com/openai/codex/blob/rust-v0.158.0/codex-rs/models-manager/models.json). Apply all of these edits to that entry:
129
130| Field | Required edit |
131| ---------------------------- | ----------------------------------------------------------------------- |
132| `slug` | Set to `"company-coding-model"`, matching the LiteLLM alias. |
133| `visibility` | Set to `"list"`. |
134| `availability_nux` | Set to `null`. |
135| `upgrade` | Set to `null`. |
136| `use_responses_lite` | Set to `false`. |
137| `tool_mode` | Set to `null`. |
138| `supported_reasoning_levels` | Remove the entry whose `effort` is `"ultra"`; retain the other entries. |
139| `additional_speed_tiers` | Set to `[]`. |
140| `service_tiers` | Set to `[]`. |
141| `default_service_tier` | Set to `null`. |
142| `web_search_tool_type` | Set to `"text"`. |
143| `multi_agent_version` | Set to `"v1"`. |
144| `supports_search_tool` | Set to `false` for Runtime. |
145
146Preserve the remaining fields, including the model's instructions and context limits. Keep the edited entry in the catalog's top-level `models` array. These changes mirror the released [Bedrock metadata adjustments](https://github.com/openai/codex/blob/rust-v0.158.0/codex-rs/model-provider/src/amazon_bedrock/catalog.rs) and [Runtime search restriction](https://github.com/openai/codex/blob/rust-v0.158.0/codex-rs/model-provider/src/amazon_bedrock/runtime_catalog.rs). Recheck them against the matching source when changing the client version or upstream model.
147
148Distribute the complete JSON file and configure `model_catalog_json` using [Roll out a gateway](https://learn.chatgpt.com/docs/enterprise/roll-out-a-gateway#supply-metadata-for-a-custom-alias). Keep `web_search = "disabled"` in the Runtime client configuration. Verify the edited catalog through the gateway before distributing it to more users.
149
150### Verify Responses support
151
152Expose `POST /v1/responses` at the client-facing HTTPS endpoint. Configure the load balancer and any reverse proxy to pass streaming events without buffering. Preserve follow-up turns and function-call results. A working Chat Completions endpoint alone isn't sufficient for this connection.
153
154Complete the checks in [Gateway compatibility](https://learn.chatgpt.com/docs/enterprise/gateway-compatibility) before distributing client configuration. Test through the same host name, network controls, and authentication path your users will use.
155
156### Issue a test credential
157
158Create a scoped LiteLLM virtual key for one test user. Restrict it to the approved alias and configure expiration, rate limits, and a budget. See LiteLLM's [virtual-key documentation](https://docs.litellm.ai/docs/proxy/virtual_keys) for the applicable controls.
159
160Distribute the key through your secret-management process or an authentication helper. Don't give users the LiteLLM administrative key or embed gateway credentials in `config.toml`.
161
162### Verify the user connection
163
164Complete these checks before expanding access:
165
1661. Confirm that the HTTPS certificate matches the gateway host name and the service is healthy.
1672. Connect one user through [Connect to a gateway](https://learn.chatgpt.com/docs/enterprise/connect-to-a-gateway).
1683. Run a short prompt, a follow-up turn, and a read-only tool task.
1694. Confirm that gateway records show the expected identity, alias, and upstream route without exposing credentials or sensitive prompt content.
1705. Test credential expiration or revocation and confirm that unauthorized model aliases are rejected.
171
172Keep the deployed image version, route configuration, and test results with your rollout record. Continue with [Roll out a gateway](https://learn.chatgpt.com/docs/enterprise/roll-out-a-gateway) for team distribution and ongoing operations.
173
174## Troubleshoot the connection
175
176Use the failing layer to narrow the problem:
177
178| Symptom | What to check |
179| ------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
180| HTTPS fails before inference | DNS, certificate host name, load-balancer health, and allowed client networks. |
181| Gateway returns `401` or `403` | Distinguish a rejected user credential from an upstream Bedrock authentication or permission failure using gateway logs. |
182| Requested model isn't found | Confirm the exact client-facing alias and its upstream model or inference-profile mapping. |
183| Request is blocked before reaching LiteLLM | Check load-balancer and web application firewall logs, including request-body limits. Preserve your security controls while testing representative Codex requests. |
184| Text works, but a turn doesn't finish | Check streaming buffers, timeouts, terminal events, and the follow-up and tool-call checks in Gateway compatibility. |
185| Upstream request times out | Check model availability in the source Region, routing configuration, quotas, and gateway logs before changing timeouts. |
186
187Retest the same user path after a fix. A successful gateway health check doesn't verify an authenticated inference request or a complete Codex turn.