
guides/rft-use-cases.md +0 −500 deleted
File Deleted View Diff
1# Reinforcement fine-tuning use cases
2
3> For the complete documentation index, see [llms.txt](/llms.txt). Markdown versions of documentation pages are available by appending `.md` to the page URL.
4
5[Reinforcement fine-tuning](https://developers.openai.com/api/docs/guides/reinforcement-fine-tuning) (RFT) provides a way to improve your model's performance at specific tasks. The task must be clear and have verifiable answers.
6
7OpenAI is winding down the fine-tuning platform. The platform is no longer
8 accessible to new users, but existing users of the fine-tuning platform will
9 be able to create training jobs for the coming months.
10
11
12 All fine-tuned models will remain available for inference until their base
13 models are [deprecated](https://developers.openai.com/api/docs/deprecations). The full timeline is
14 [here](https://developers.openai.com/api/docs/deprecations).
15
16## When to use reinforcement fine-tuning
17
18An agentic workflow is designed to make decisions that are both correct and verifiable. RFT can help by providing explicit rubrics and using code‑based or LLM‑based graders to measure functional success, factual accuracy, or policy compliance.
19
20Across early users, three clear use cases have emerged:
21
221. **Turn instructions into working code**: Convert open-ended prompts into structured code, configs, or templates that must pass deterministic tests.
231. **Pull facts into a clean format**: Extract verifiable facts and summaries from messy, unstructured text and return JSON-structured or other schema-based outputs.
241. **Apply complex rules correctly**: Make fine-grained label or policy decisions when the information provided is nuanced, large in quantity, hierarchical, or high-stakes.
25
26[Ready to use reinforcement fine-tuning? Skip to the guide →](https://developers.openai.com/api/docs/guides/reinforcement-fine-tuning)
27
28### 1. Turn instructions into working code
29
30In this use case, models reason over hidden domain constraints to produce structured outputs like code, queries, or infrastructure templates. Outputs must satisfy multiple correctness conditions, and success is usually deterministically graded: the artifact either compiles, passes tests, or meets an explicit schema.
31
32#### Wiring verification IPs for semiconductor design
33
34
35
36Use case
37
38
39
40> **Company**: [ChipStack](https://www.chipstack.ai) is building the next-generation of AI-powered tools for chip design and verification, aimed at significantly reducing the time and cost of developing and validating complex semiconductor chips.
41>
42> **Problem to solve**: One task that's challenging and time-consuming for humans is binding design interfaces to verification IPs (pre-created verification components that, when properly applied, can significantly enhance quality and coverage of verification). There are many verification IPs, and each can contain dozens to hundreds of signals that may be mapped. Someone must understand this domain well in order to apply the verification IP correctly.
43>
44> **Objective**: To train OpenAI reasoning models to do this instead, ChipStack prepared a dataset consisting of less than 50 samples, then performed several RFT variations. For the final evaluation report, they ran this evaluation set three times against each model and variation—o1-mini base and fine-tuned, o3-mini base and fine-tuned—and averaged the results per-sample then overall.
45
46
47
48
49
50
51
52Prompt
53
54
55
56> Below is a piece of example data provided.
57
58```text
59[
60 {“name”: “BLOCK_SIZE”, “value”: “8”},
61 {“name”: “ADDR_WIDTH”, “value”: “4”}
62]
63```
64
65
66
67
68
69
70
71Grader code
72
73
74
75> Below is a grader definition in Python of a string map, represented as a list of objects with `name` and `value` properties.
76>
77> Conceptually, this is meant to model a type like `Dict[str, str]`.
78
79```python
80{
81 "type": "python",
82 "name": "donors_caas",
83 "image_tag": "alpha",
84 "source": """from collections import Counter
85
86def grade(sample: dict[str, str], item: dict[str, str]) -> float:
87 # multisets of (name, value) pairs
88 predicted = sample["output_json"]["predicted"]
89 expected = item["reference_answer"]
90 pred_counts = Counter((d["name"], d["value"]) for d in predicted)
91 exp_counts = Counter((d["name"], d["value"]) for d in expected)
92
93 true_pos = sum(min(pred_counts[p], exp_counts[p]) for p in pred_counts)
94 pred_total = sum(pred_counts.values())
95 exp_total = sum(exp_counts.values())
96
97 precision = true_pos / pred_total if pred_total else 0.0
98 recall = true_pos / exp_total if exp_total else 0.0
99
100 if precision + recall == 0.0:
101 return 0.0
102 return 2 * precision * recall / (precision + recall)""",
103}
104```
105
106
107
108
109
110
111
112Results
113
114
115
116> For both o1-mini and o3-mini, performance improved by ~12 percentage points. The fine-tuned variants got much better about recognizing when not to apply wiring. Many commercial verification IPs can contain hundreds of optional signals, most of which are not meant to be applied.
117>
118> "Thanks to powerful base models and easy-to-use Reinforced Fine-Tuning APIs, we were able to significantly boost performance on our task with a small set of high-quality samples."
119>
120> —[ChipStack](https://www.chipstack.ai), next-generation of AI-powered tools for chip design and verification
121
122
123
124#### Correct handling of conflicts and dupes in a schedule manager
125
126
127
128Use case
129
130
131
132> **Company**: [Milo](https://www.joinmilo.com) helps busy parents manage chaotic family schedules by converting messy inputs—like text convos with to-dos, school newsletter PDFs, weekly reminders, sports schedule emails—into reliable calendar and list actions.
133>
134> **Problem to solve**: Base GPT-4o prompting and SFT fell short of trust thresholds.
135>
136> **Objective**: Milo used RFT to properly create coding tasks like event vs. list classification, recurrence rule generation, accurate updates and deletes, conflict detection, and strict output formatting. They defined a grader that checked whether generated item objects were complete, categorized correctly, and were a duplicate or had a calendar conflict.
137
138
139
140
141
142
143
144Results
145
146
147
148> Results showed performance improvements across the board, with average correctness scores **increasing from 0.86 to 0.91**, while the most challenging scenarios improved from **0.46 to 0.71** (where a perfect score=1).
149>
150> "Accuracy isn't just a metric—it's peace of mind for busy parents. These are still early days but with such important improvements in base performance, we're able to push more aggressively into complex reasoning needs."
151>
152> "Navigating and supporting family dynamics involves understanding nuanced implications of the data. Take conflicts—knowing soccer for Ethan conflicts with Ella's recital because Dad has to drive both kids goes deeper than simple overlapping times."
153>
154> —[Milo](https://www.joinmilo.com), AI scheduling tool for families
155
156
157
158### 2. Pull facts into a clean format
159
160These tasks typically involve subtle distinctions that demand clear classification guidelines. Successful framing requires explicit and hierarchical labeling schemes defined through consensus by domain experts. Without consistent agreement, grading signals become noisy, weakening RFT effectiveness.
161
162#### Assigning ICD-10 medical codes
163
164
165
166Use case
167
168
169
170> **Company**: [Ambience](https://www.ambiencehealthcare.com) is an AI platform that eliminates administrative burden for clinicians and ensures accurate, compliant documentation across 100+ specialties, helping physicians focus on patient care while increasing documentation quality and reducing compliance risk for health systems.
171>
172> **Problem to solve**: ICD-10 coding is one of the most intricate administrative tasks in medicine. After every patient encounter, clinicians must map each diagnosis to one of ~70,000 codes—navigating payor-specific rules on specificity, site-of-care, and mutually exclusive pairings. Errors can trigger audits and fines that stretch into nine figures.
173>
174> **Objective**: Using reinforcement fine-tuning on OpenAI frontier models, Ambience wanted to train a reasoning system that listens to the visit audio, pulls in relevant EHR context, and recommends ICD-10 codes with accuracy exceeding expert clinicians.
175
176
177
178
179
180
181
182Results
183
184
185
186> Ambience achieved model improvements that can lead human experts.
187>
188> On a gold-panel test set spanning hundreds of encounters, reinforcement fine-tuning moved the model from trailing humans to leading them by **12 points—eliminating roughly one quarter of the coding errors trained physicians make**:
189>
190> - o3-mini (base): 0.39 (-6 pts)
191> - Physician baseline: 0.45
192> - RFT-tuned o3-mini: 0.57 (+12 pts)
193>
194> The result is a real-time, point-of-care coding support that can raise reimbursement integrity while reducing compliance risk.
195>
196> “Accurate ICD-10 selection is mission-critical for compliant documentation. RFT unlocked a new level of coding precision we hadn’t seen from any foundation model and set a new bar for automated coding.”
197>
198> —[Ambience Healthcare](https://www.ambiencehealthcare.com)
199
200
201
202#### Extracting excerpts to support legal claims
203
204
205
206Use case
207
208
209
210> **Company**: [Harvey](https://www.harvey.ai) is building AI that legal teams trust—and that trust hinges on retrieving precisely the right evidence from a sprawling corpora of contracts, statutes, and case law. Legal professionals aren’t satisfied with models that merely generate plausible-sounding summaries or paraphrased answers. They demand verifiable citations—passages that can be traced directly back to source documents.
211>
212> **Problem to solve**: Harvey’s clients use its models to triage litigation risk, construct legal arguments, and support due diligence for legal professionals—all tasks where a single missed or misquoted sentence can flip an outcome. Models must be able to parse long, dense legal documents and extract only the portions that matter.
213> In practice, these inputs are often messy and inconsistent: some claims are vague, while others hinge on rare legal doctrines buried deep in boilerplate.
214>
215> **Objective**: The task’s requirements are to interpret nuanced legal claims, navigate long-form documents, and select on-point support with verbatim excerpts.
216
217
218
219
220
221
222
223Prompt
224
225
226
227```text
228## Instructions
229You will be provided with a question and a text excerpt. Identify any passages in the text that are directly relevant to answering the question.
230- If there are no relevant passages, return an empty list.
231- Passages must be copied **exactly** from the text. Do not paraphrase or summarize.
232## Excerpt
233"""{text_excerpt}"""
234```
235
236
237
238
239
240
241
242Grader
243
244
245
246```python
247from rapidfuzz import fuzz
248
249
250# Similarity ratio helper
251def fuzz_ratio(a: str, b: str) -> float:
252 """Return a normalized similarity ratio using RapidFuzz."""
253 if len(a) == 0 and len(b) == 0:
254 return 1.0
255 return fuzz.ratio(a, b) / 100.0
256
257
258# Main grading entrypoint (must be named \`grade\`)
259def grade(sample: dict, item: dict) -> float:
260 """Compute an F1‑style score for citation extraction answers using RapidFuzz."""
261 model_passages = (sample.get("output_json") or {}).get("passages", [])
262 ref_passages = (item.get("reference_answer") or {}).get("passages", [])
263
264 # If there are no reference passages, return 0.
265 if not ref_passages:
266 return 0.0
267
268 # Recall: average best match for each reference passage.
269 recall_scores = []
270 for ref in ref_passages:
271 best = 0.0
272 for out in model_passages:
273 score = fuzz_ratio(ref, out)
274 if score > best:
275 best = score
276 recall_scores.append(best)
277 recall = sum(recall_scores) / len(recall_scores)
278
279 # Precision: average best match for each model passage.
280 if not model_passages:
281 precision = 0.0
282 else:
283 precision_scores = []
284 for out in model_passages:
285 best = 0.0
286 for ref in ref_passages:
287 score = fuzz_ratio(ref, out)
288 if score > best:
289 best = score
290 precision_scores.append(best)
291 precision = sum(precision_scores) / len(precision_scores)
292
293 if precision + recall == 0:
294 return 0.0
295
296 return 2 * precision * recall / (precision + recall)
297```
298
299
300
301
302
303
304
305Results
306
307
308
309> After reinforcement fine-tuning, Harvey saw a **20% increase** in the F1 score:
310>
311> - Baseline F1: 0.563
312> - Post-RFT F1 - 0.6765
313>
314> Using RFT, Harvey significantly improved legal fact-extraction performance, surpassing GPT-4o efficiency and accuracy. Early trials showed RFT **winning or tying in 93% of comparisons** against GPT-4o.
315>
316> “The RFT model demonstrated comparable or superior performance to GPT-4o, but with significantly faster inference, proving particularly beneficial for real-world legal use cases.
317>
318> —[Harvey](https://www.harvey.ai), AI for legal teams
319
320
321
322### 3. Apply complex rules correctly
323
324This use case involves pulling verifiable facts or entities from unstructured inputs into defined schemas (for example, JSON objects, condition codes, medical codes, legal citations, or financial metrics).
325
326Successful extraction tasks typically benefit from precise, continuous grading methodologies—like span-level F1 scores, fuzzy text-matching metrics, or numeric accuracy checks—to evaluate how accurately the extracted information aligns with ground truth. Define explicit success criteria and detailed rubrics. Then, the model can achieve reliable, repeatable improvements.
327
328#### Expert-level reasoning in tax analysis
329
330
331
332Use case
333
334
335
336> **Company**: [Accordance](https://www.accordance.com) is building a platform for tax, audit, and CPA teams.
337>
338> **Problem to solve**: Taxation is a highly complex domain, requiring deep reasoning across nuanced fact patterns and intricate regulations. It's also a field that continues changing.
339>
340> **Objective**: Accordance wanted a high-trust system for sophisticated tax scenarios while maintaining accuracy. Unlike traditional hardcoded software, it's important that their data extraction tool adapts as the tax landscape evolves.
341
342
343
344
345
346
347
348Grader code
349
350
351
352```text
353[+0.05] For correctly identifying Alex (33.33%), Barbara (33.33% → 20%), Chris (33.33%), and Dana (13.33%) ownership percentages
354[+0.1] For correctly calculating Barbara's annual allocation as 26.67% and Dana's as 6.67% without closing of books
355[+0.15] For properly allocating Alex ($300,000), Barbara ($240,030), Chris ($300,000), and Dana ($60,030) ordinary income
356[+0.1] For calculating Alex's ending stock basis as $248,333 and debt basis as $75,000
357[+0.05] For calculating Barbara's remaining basis after sale as $264,421
358[+0.1] For calculating AAA before distributions as $1,215,000 and ending AAA as $315,000
359[+0.1] For identifying all distributions as tax-free return of capital under AAA
360[+0.1] For calculating Barbara's capital gain on stock sale as $223,720 ($400,000 - $176,280)
361[+0.1] For explaining that closing of books would allocate based on actual half-year results
362[+0.05] For identifying the ordering rules: AAA first, then E&P ($120,000), then remaining basis
363[+0.05] For noting distributions exceeding $1,215,000 would be dividends up to $120,000 E&P
364[+0.05] For correctly accounting for separately stated items in basis calculations (e.g., $50,000 Section 1231 gain)
365```
366
367
368
369
370
371
372
373Results
374
375
376
377> By collaborating with OpenAI and their in-house tax experts, Accordance achieved:
378>
379> - Almost **40% improvement** in tax analysis tasks over base models
380> - Superior performance compared to all other leading models on benchmarks like TaxBench
381> - The RFT-trained models demonstrated an ability to handle advanced tax scenarios with high accuracy—when evaluated by tax professionals, Accordance’s fine-tuned models showed expert-level reasoning, with the potential to save thousands of hours of manual work
382>
383> “We’ve achieved a 38.89% improvement in our tax analysis tasks over base models and significantly outperformed all other leading models on key tax benchmarks (including TaxBench). The RFT-trained models’ abilities to handle sophisticated tax scenarios while maintaining accuracy demonstrates the readiness of reinforcement fine-tuning—and AI more broadly—for professional applications. Most importantly, RFT provides a foundation for continuous adaptation as the tax landscape evolves, ensuring sustained value and relevance. When evaluated by tax experts, our fine-tuned models demonstrated expert-level reasoning capabilities that will save thousands of professional hours—this isn’t just an incremental improvement, it’s a paradigm shift in how tax work can be done.”
384>
385> —[Accordance](https://www.accordance.com/), AI tax accounting company
386
387
388
389#### Enforcement of nuanced content moderation policies
390
391
392
393Use case
394
395
396
397> **Company**: [SafetyKit](https://www.safetykit.com) is a risk and compliance platform that helps organizations make decisions across complex content moderation workflows.
398>
399> **Problem to solve**: These systems must handle large volumes of content and apply intricate policy logic that requires multistep reasoning. Because of the volume of data and subtle distinctions in labelling, these types of tasks can be difficult for general purpose models.
400>
401> **Objective**: SafetyKit aimed to replace multiple nodes in their most complex workflows with a single reasoning agent using a reinforcement fine-tuned model. The goal is to reduce SafetyKit’s time-to-market for novel policy enforcements even in challenging, nuanced domains.
402
403
404
405
406
407
408
409Results
410
411
412
413> SafetyKit is using their o3-mini RFT model to support advanced content moderation capabilities, ensuring user safety for one of the largest AI chatbot companies in the world. They have successfully improved F1-score **from 86% to 90%**, soon to replace dozens of 4o calls within their production pipeline.
414>
415> "SafetyKit’s RFT-enabled moderation achieved substantial improvements in nuanced content moderation tasks, crucial for safeguarding users in dynamic, real-world scenarios."
416>
417> —[SafetyKit](https://www.safetykit.com)
418
419
420
421#### Legal document reviews, comparisons, and summaries
422
423
424
425Use case
426
427
428
429> **Company**: [Thomson Reuters](https://www.thomsonreuters.com) is an AI and technology company empowering professionals with trusted content and workflow automation.
430>
431> **Problem to solve**: Legal professionals must read through large amounts of content before making any decisions. Thomson Reuter's CoCounsel product is designed to help these experts move faster by providing an AI assistant with content and industry knowledge. The models that power this tool must understand complex legal rules.
432>
433> **Objective**: Thomson Reuters aimed to create a reinforcement fine-tuned model excelling in legal AI skills. They conducted preliminary evaluations of RFT to see if they could achieve model performance improvements, using specialized datasets from three highly-used CoCounsel Legal AI skills for legal professionals:
434>
435> 1. Review documents: Generates detailed answers to questions asked against contracts, transcripts, and other legal documents
436> 1. Compare documents: Highlights substantive differences between two or more different contracts or documents
437> 1. Summarize: Summarizes the most important information within one or more documents to enable rapid legal review
438
439
440
441
442
443
444
445Results
446
447
448
449> 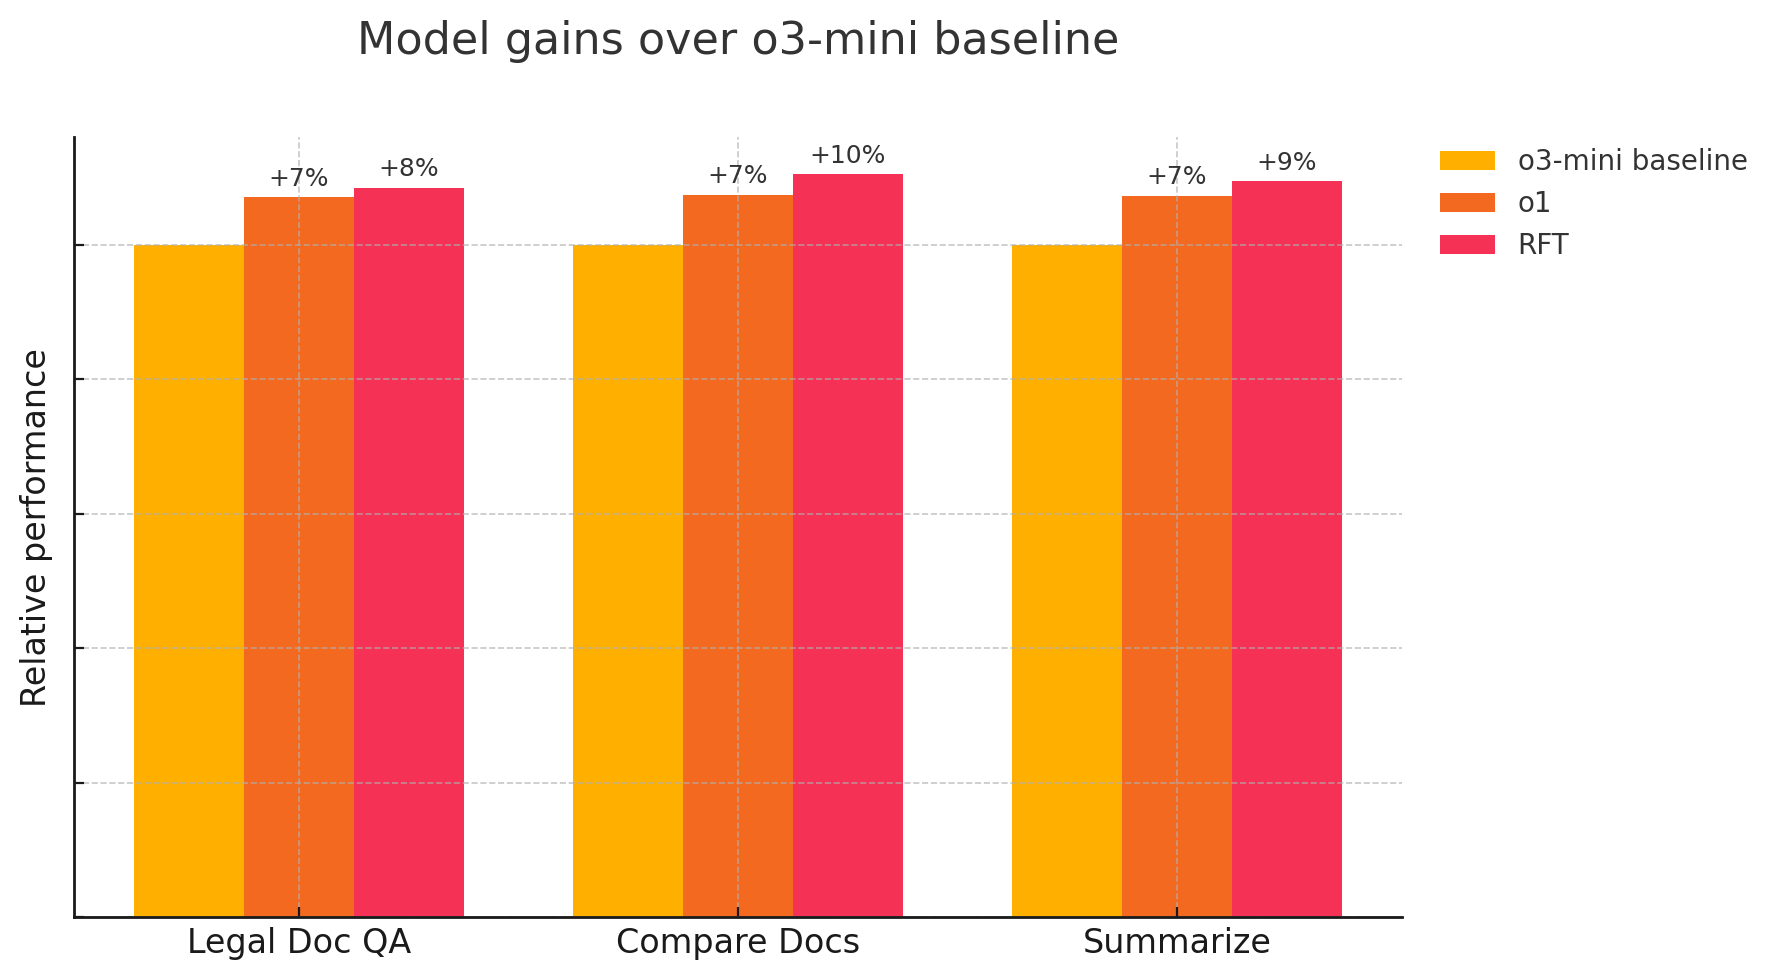
450>
451> "LLM as a judge has been helpful in demonstrating the possibility of improving upon the reasoning models - in preliminary evaluations, the RFT model consistently performed better than the baseline o3-mini and o1 model"
452>
453> —[Thomson Reuters](https://www.thomsonreuters.com/), AI and technology company
454
455
456
457## Evals are the foundation
458
459**Before implementing RFT, we strongly recommended creating and running an eval for the task you intend to fine-tune on**. If the model you intend to fine-tune scores at either the absolute minimum or absolute maximum possible score, then RFT won’t be useful to you.
460
461RFT works by reinforcing better answers to provided prompts. If we can’t distinguish the quality of different answers (that is, if they all receive the minimum or maximum possible score), then there's no training signal to learn from. However, if your eval scores somewhere in the range between the minimum and maximum possible scores, there's enough data to work with.
462
463An effective eval reveals opportunities where human experts consistently agree but current frontier models struggle, presenting a valuable gap for RFT to close. [Get started with evals](https://developers.openai.com/api/docs/guides/evals).
464
465## How to get better results from RFT
466
467To see improvements in your fine-tuned model, there are two main places to revisit and refine: making sure your task is well defined, and making your grading scheme more robust.
468
469<a id="reframe-or-clarify-your-task"></a>
470
471### Revise or clarify your task
472
473Good tasks give the model a fair chance to learn and let you quantify improvements.
474
475- **Start with a task the model can already solve occasionally**. RFT works by sampling many answers, keeping what looks best, and nudging the model toward those answers. If the model never gets the answer correct today, it cannot improve.
476- **Make sure each answer can be graded**. A grader must read an answer and produce a score without a person in the loop. We support multiple [grader types](https://developers.openai.com/api/docs/guides/graders), including custom Python graders and LLM judges. If you can't write code to judge the answer with an available grader, RFT is not the right tool.
477- **Remove doubt about the “right” answer**. If two careful people often disagree on the solution, the task is too fuzzy. Rewrite the prompt, add context, or split the task into clearer parts until domain experts agree.
478- **Limit lucky guesses**. If the task is multiple choice with one best option, the model can win by chance. Add more classes, ask for short open‑ended text, or tweak the format so guessing is costly.
479
480### Strengthen your grader
481
482Clear, robust grading schemes are essential for RFT.
483
484- **Produce a smooth score, not a pass/fail stamp**. A score that shifts gradually as answers improve provides a better training signal.
485- **Guard against reward hacking**. This happens when the model finds a shortcut that earns high scores without real skill.
486- **Avoid skewed data**. Datasets in which one label shows up most of the time invite the model to guess that label. Balance the set or up‑weight rare cases so the model must think.
487- **Use an LLM judge when code falls short**. For rich, open‑ended answers, have a [separate OpenAI model grade](https://developers.openai.com/api/docs/guides/graders#model-graders) your fine-tuned model's answers. Make sure you:
488 - **Evaluate the judge**: Run multiple candidate responses and correct answers through your LLM judge to ensure the grade returned is stable and aligned with preference.
489 - **Provide few-shot examples**. Include great, fair, and poor answers in the prompt to improve the grader's effectiveness.
490
491Learn more about [grader types](https://developers.openai.com/api/docs/guides/graders).
492
493## Other resources
494
495For more inspiration, visit the [OpenAI Cookbook](https://developers.openai.com/cookbook), which contains example code and links to third-party resources, or learn more about our models and reasoning capabilities:
496
497- [Meet the models](https://developers.openai.com/api/docs/models)
498- [Reinforcement fine-tuning guide](https://developers.openai.com/api/docs/guides/reinforcement-fine-tuning)
499- [Graders](https://developers.openai.com/api/docs/guides/graders)
500- [Model optimization overview](https://developers.openai.com/api/docs/guides/model-optimization)